flash-attention vs TensorRT-LLM
flash-attention and TensorRT-LLM share 7 technologies: apache-tvm-ffi, NVIDIA, quack-kernels, torch-c-dlpack-ext, torch, einops, and triton. Both are written in Python.
 LinkedIn
What they share and what sets them apart
flash-attention
Fast and memory-efficient exact attention
Python25.3kRead on November 16, 2026, at commit 328dd7bWhat is flash-attention built with?Only in flash-attention
- triton-windows
In common
apache-tvm-ffi
NVIDIA
- quack-kernels
- torch-c-dlpack-ext
- torch
- einops
- triton
TensorRT-LLM
TensorRT LLM provides users with an easy-to-use Python API to define Large Language Models (LLMs) and supports state-of-the-art optimizations to perform inference efficiently on NVIDIA GPUs. TensorRT LLM also contains components to create Python and C++ runtimes that orchestrate the inference execution in a performant way.
Python15kRead on November 8, 2026, at commit b433473What is TensorRT-LLM built with?Only in TensorRT-LLM
FastAPI
- blobfile
h5py
- pyzmq
 OpenAI
- anyio
uvicorn
starlette
- Rich
matplotlib
Plotly
accelerate
- cuda-python
flash-linear-attention
flashinfer-python
nvidia-cudnn-frontend
openai-codex
- openai-harmony
optimum
- rouge
rouge-score
- sentencepiece
- tiktoken
torchao
- transformers
diffusers
safetensors
torchvision
- datasets
- flash-attn
xgrammar
librosa
- MCP
- mistral-common
partial-json-parser
- tritonclient
evaluate
- llguidance
lm-eval
peft
- jsonlines
pillow
- jinja2
- mako
- Pydantic
msgspec
- jsonschema
opentelemetry-api
- opentelemetry-semantic-conventions-ai
psutil
prometheus-client
- boto3
- OpenTelemetry
- prometheus-fastapi-instrumentator
Side by side
Frequently asked questions
Which is bigger, flash-attention or TensorRT-LLM?
The proof: NVIDIA/TensorRT-LLM's code at commit b433473
Which has more GitHub stars, flash-attention or TensorRT-LLM?
The proof: Dao-AILab/flash-attention on GitHub
Which has more tests, flash-attention or TensorRT-LLM?
The proof: NVIDIA/TensorRT-LLM's code at commit b433473
Which was updated more recently, flash-attention or TensorRT-LLM?
Which has more commits signed by AI, flash-attention or TensorRT-LLM?
The proof: the commits each tool signed in Dao-AILab/flash-attention
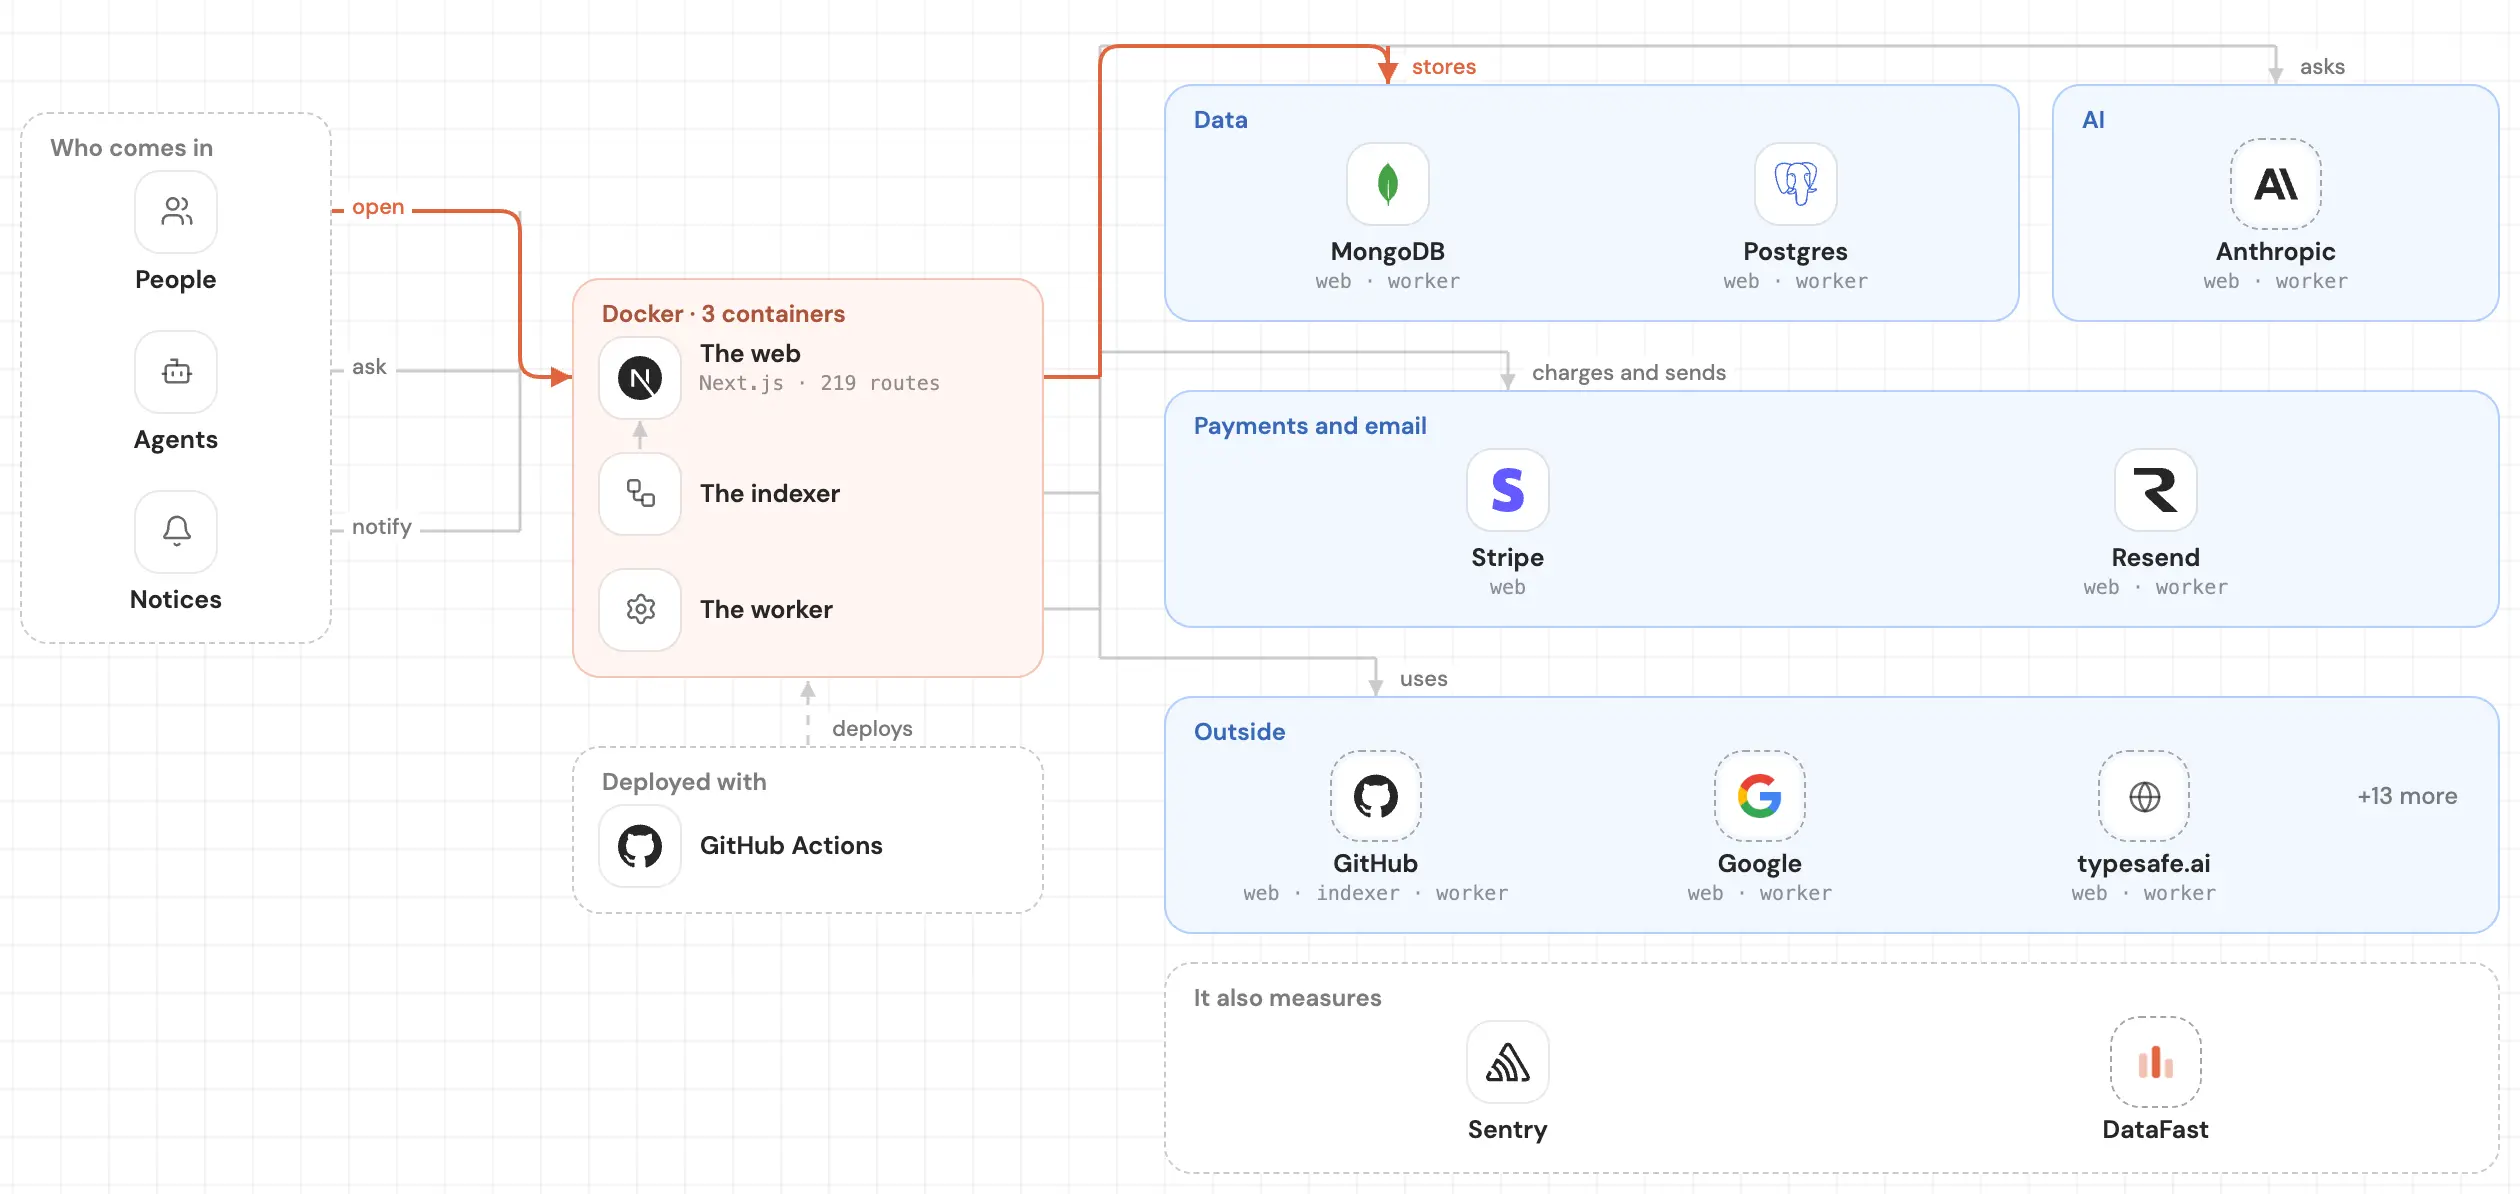
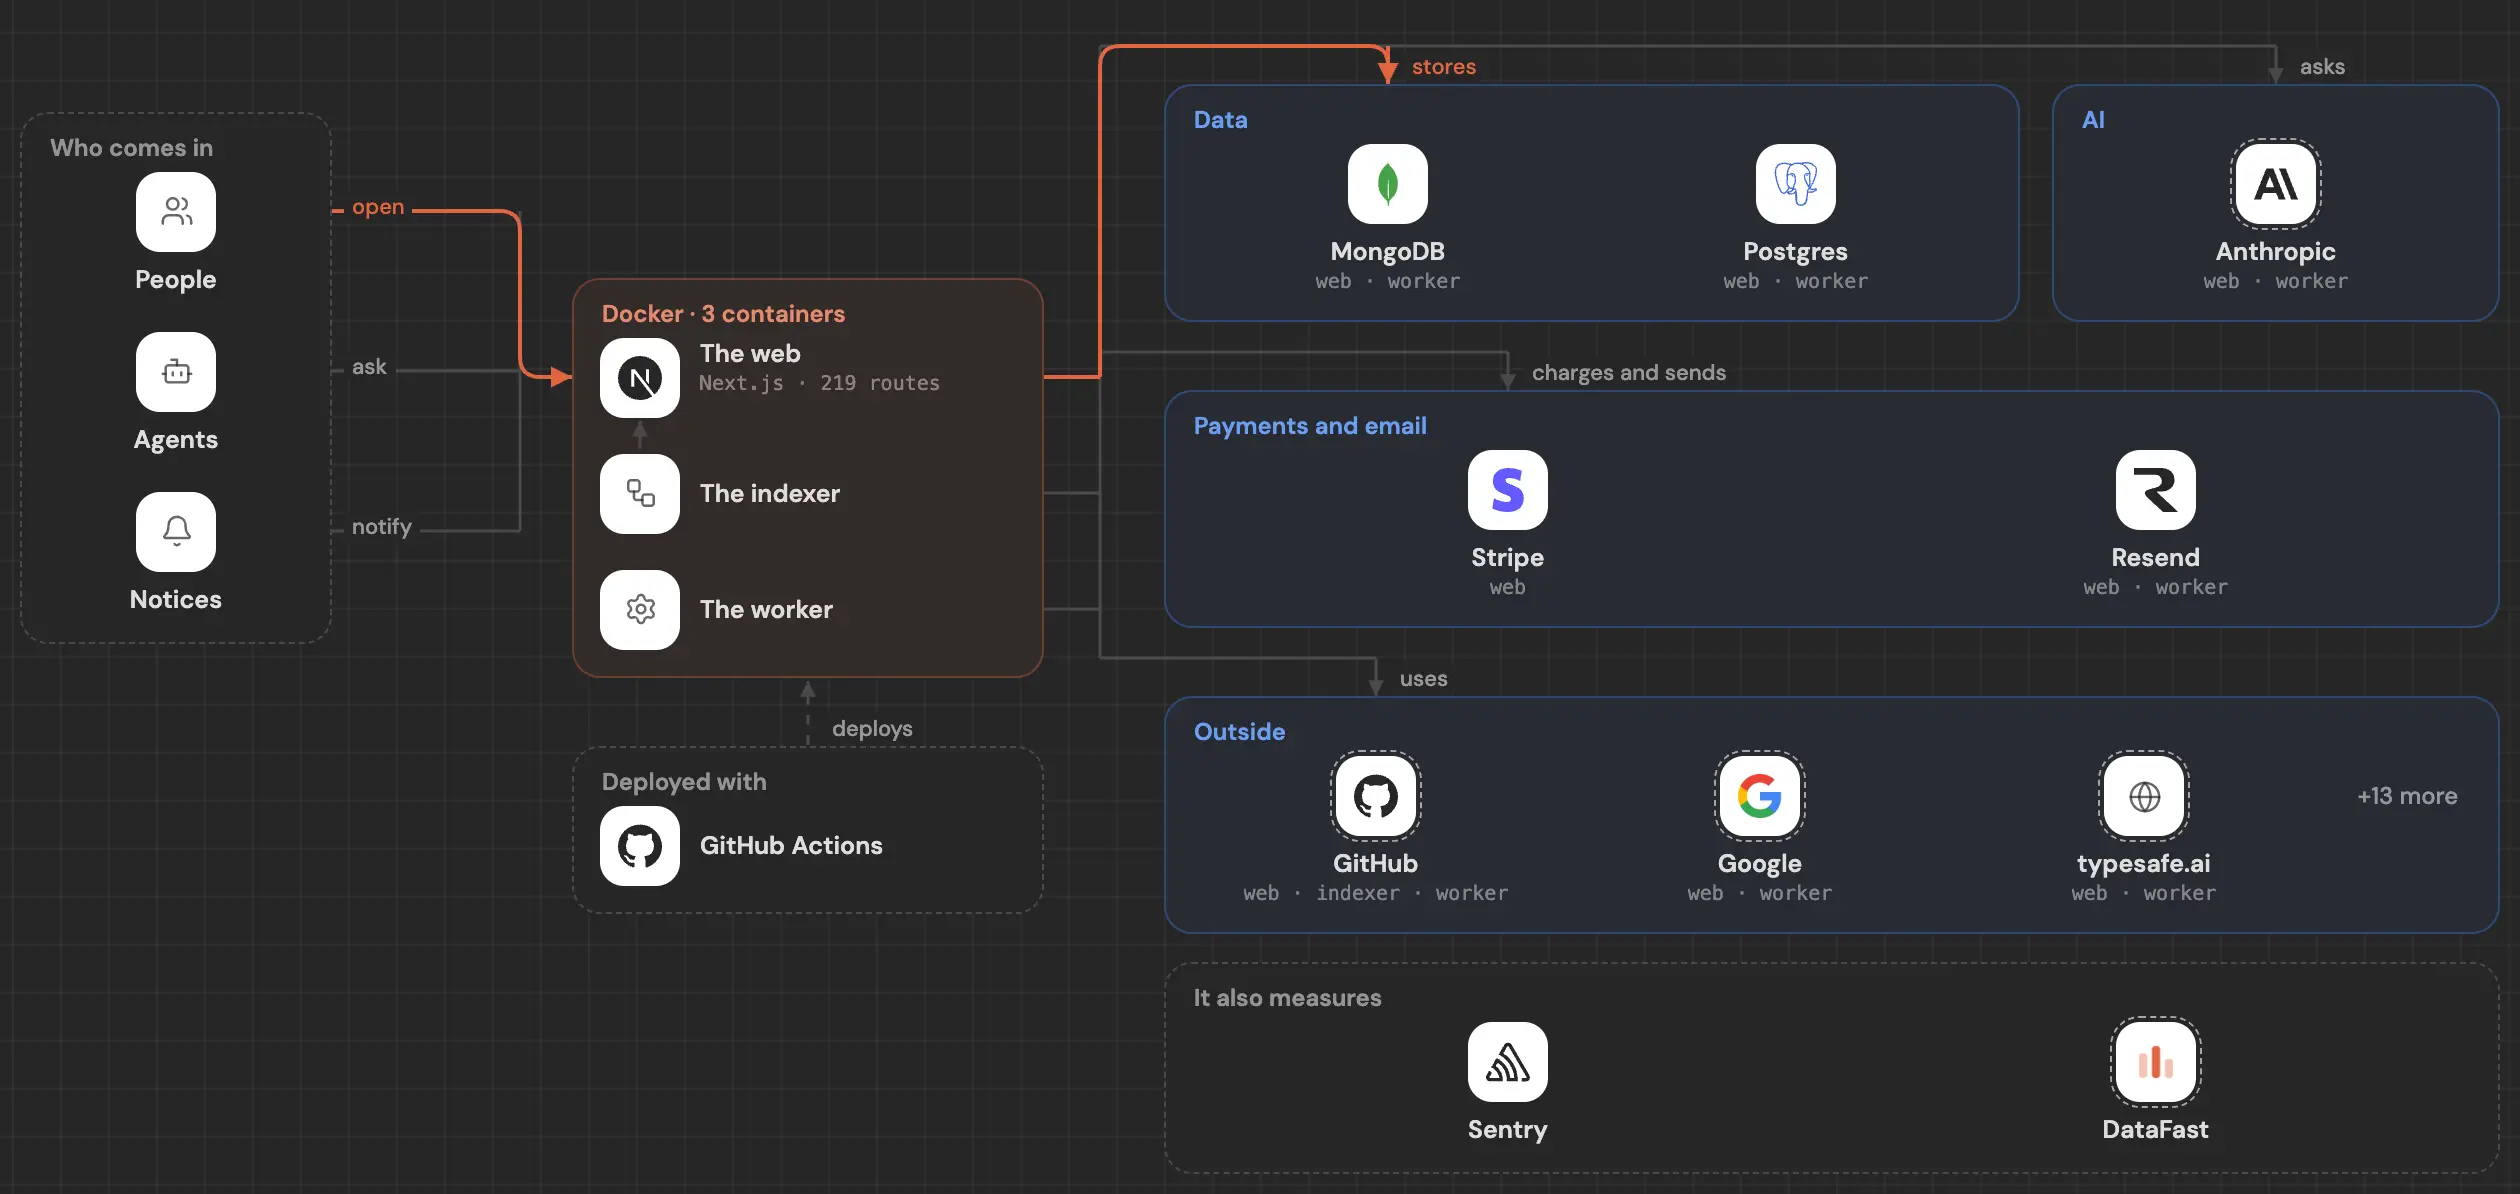
See inside your code, today.
Paste your repo and see it drawn, part by part: a medium one in under a minute.
Free, no account.Private repo? Sign in with GitHub


