flash-attention vs vllm
flash-attention and vllm share 6 technologies: apache-tvm-ffi, NVIDIA, quack-kernels, torch, einops, and triton. Both are written in Python.
 LinkedIn
What they share and what sets them apart
Dao-AILab
flash-attention
Fast and memory-efficient exact attention
Python25.3kRead on November 16, 2026, at commit 328dd7bWhat is flash-attention built with?Only in flash-attention
- torch-c-dlpack-ext
- triton-windows
In common
apache-tvm-ffi
NVIDIA
- quack-kernels
- torch
- einops
- triton
vllm-project
vllm
A high-throughput and memory-efficient inference and serving engine for LLMs
Python97.1kRead on November 17, 2026, at commit 61c3895What is vllm built with?Only in vllm
FastAPI
- axum
- gitdb
- pyzmq
- Hugging Face
- Tokio
starlette
- Ray
- AIOHTTP
- tower
mkdocs-material
- indicatif
- AMD
- auto-round-lib
- conch-triton-kernels
- cuda-bindings
- cuda-python
cupy-cuda12x
flashinfer-python
- humming-kernels
lm-format-enforcer
mooncake-transfer-engine
nvidia-cudnn-frontend
 OpenAI
- openai-harmony
- oss-harmony
- sentencepiece
- vllm-bench
- vllm-chat
- vllm-engine-core-client
- vllm-llm
- vllm-managed-engine
- vllm-parser
- vllm-proto
- vllm-server
- vllm-text
- vllm-tokenizer
- transformers
- xgrammar-structural-tag
llm-multimodal
- compressed-tensors
safetensors
- mistral-common
xgrammar
partial-json-parser
torchvision
lmcache
torchaudio
timm
vllm-xpu-kernels
- runai-model-streamer
tokenizers
tokenspeed-mla
- llguidance
- MCP
outlines-core
- tpu-inference
- fastokens
- fastsafetensors
- hf-hub
- instanttensor
- nixl
- riptoken
- tekken
- tensorizer
- tiktoken
- tiktoken-rs
- markdown
markupsafe
- mkdocs-material-extensions
parquet
- properdocs
- pymdown-extensions
selectolax
- xlsxwriter
pillow
- image
- jinja2
minijinja
- torchcodec
- annotated-types
- Pydantic
msgspec
validator
- opentelemetry-semantic-conventions-ai
- python-json-logger
- vllm-metrics
- vllm-tracing
tracing
prometheus-client
psutil
- model-hosting-container-standards
- OpenTelemetry
- prometheus-fastapi-instrumentator
Side by side
flash-attentionvllm
SizeLines written by people and agents, without generated ones; code files, without tests.
flash-attention139,521 lines written150 code files
vllm2,606,460 lines written3,630 code files
Who writes itA commit counts as AI's when it carries its signature: a Co-Authored-By line, its author name or the merge of its branch.
flash-attention1.7% of its commits signed by AIWith Claude Code, Cursor, and GitHub Copilot
vllm14.7% of its commits signed by AIWith Claude Code, Codex, Gemini CLI, Cursor, GitHub Copilot, Devin, Mistral Vibe, CodeRabbit, Factory, and Qwen Code
ActivityFrom GitHub and its history, on the day SeeRepo read it.
flash-attentionLast push November 16, 20261,613 commits25,304 stars
vllmLast push November 17, 202625,558 commits97,060 stars
TestsThe files that test the code, and the share of code files a test imports.
flash-attention80 test files32% of its code files have a test that imports them
vllm2,586 test files60.7% of its code files have a test that imports them
Frequently asked questions
Which is bigger, flash-attention or vllm?
vllm, with 2,606,460 lines written; flash-attention has 139,521.
The proof: vllm-project/vllm's code at commit 61c3895
Which has more GitHub stars, flash-attention or vllm?
vllm, with 97,060 stars; flash-attention has 25,304.
The proof: vllm-project/vllm on GitHub
Which has more tests, flash-attention or vllm?
vllm, with 2,586 test files; flash-attention has 80.
The proof: vllm-project/vllm's code at commit 61c3895
Which was updated more recently, flash-attention or vllm?
vllm: its last push was on November 17, 2026, and flash-attention's on November 16, 2026.
The proof: vllm-project/vllm's commits on GitHub
Which has more commits signed by AI, flash-attention or vllm?
vllm: an AI signed 14.7% of its commits, with Claude Code, Codex, Gemini CLI, Cursor, GitHub Copilot, Devin, Mistral Vibe, CodeRabbit, Factory, and Qwen Code; in flash-attention, 1.7%.
The proof: the commits each tool signed in vllm-project/vllm
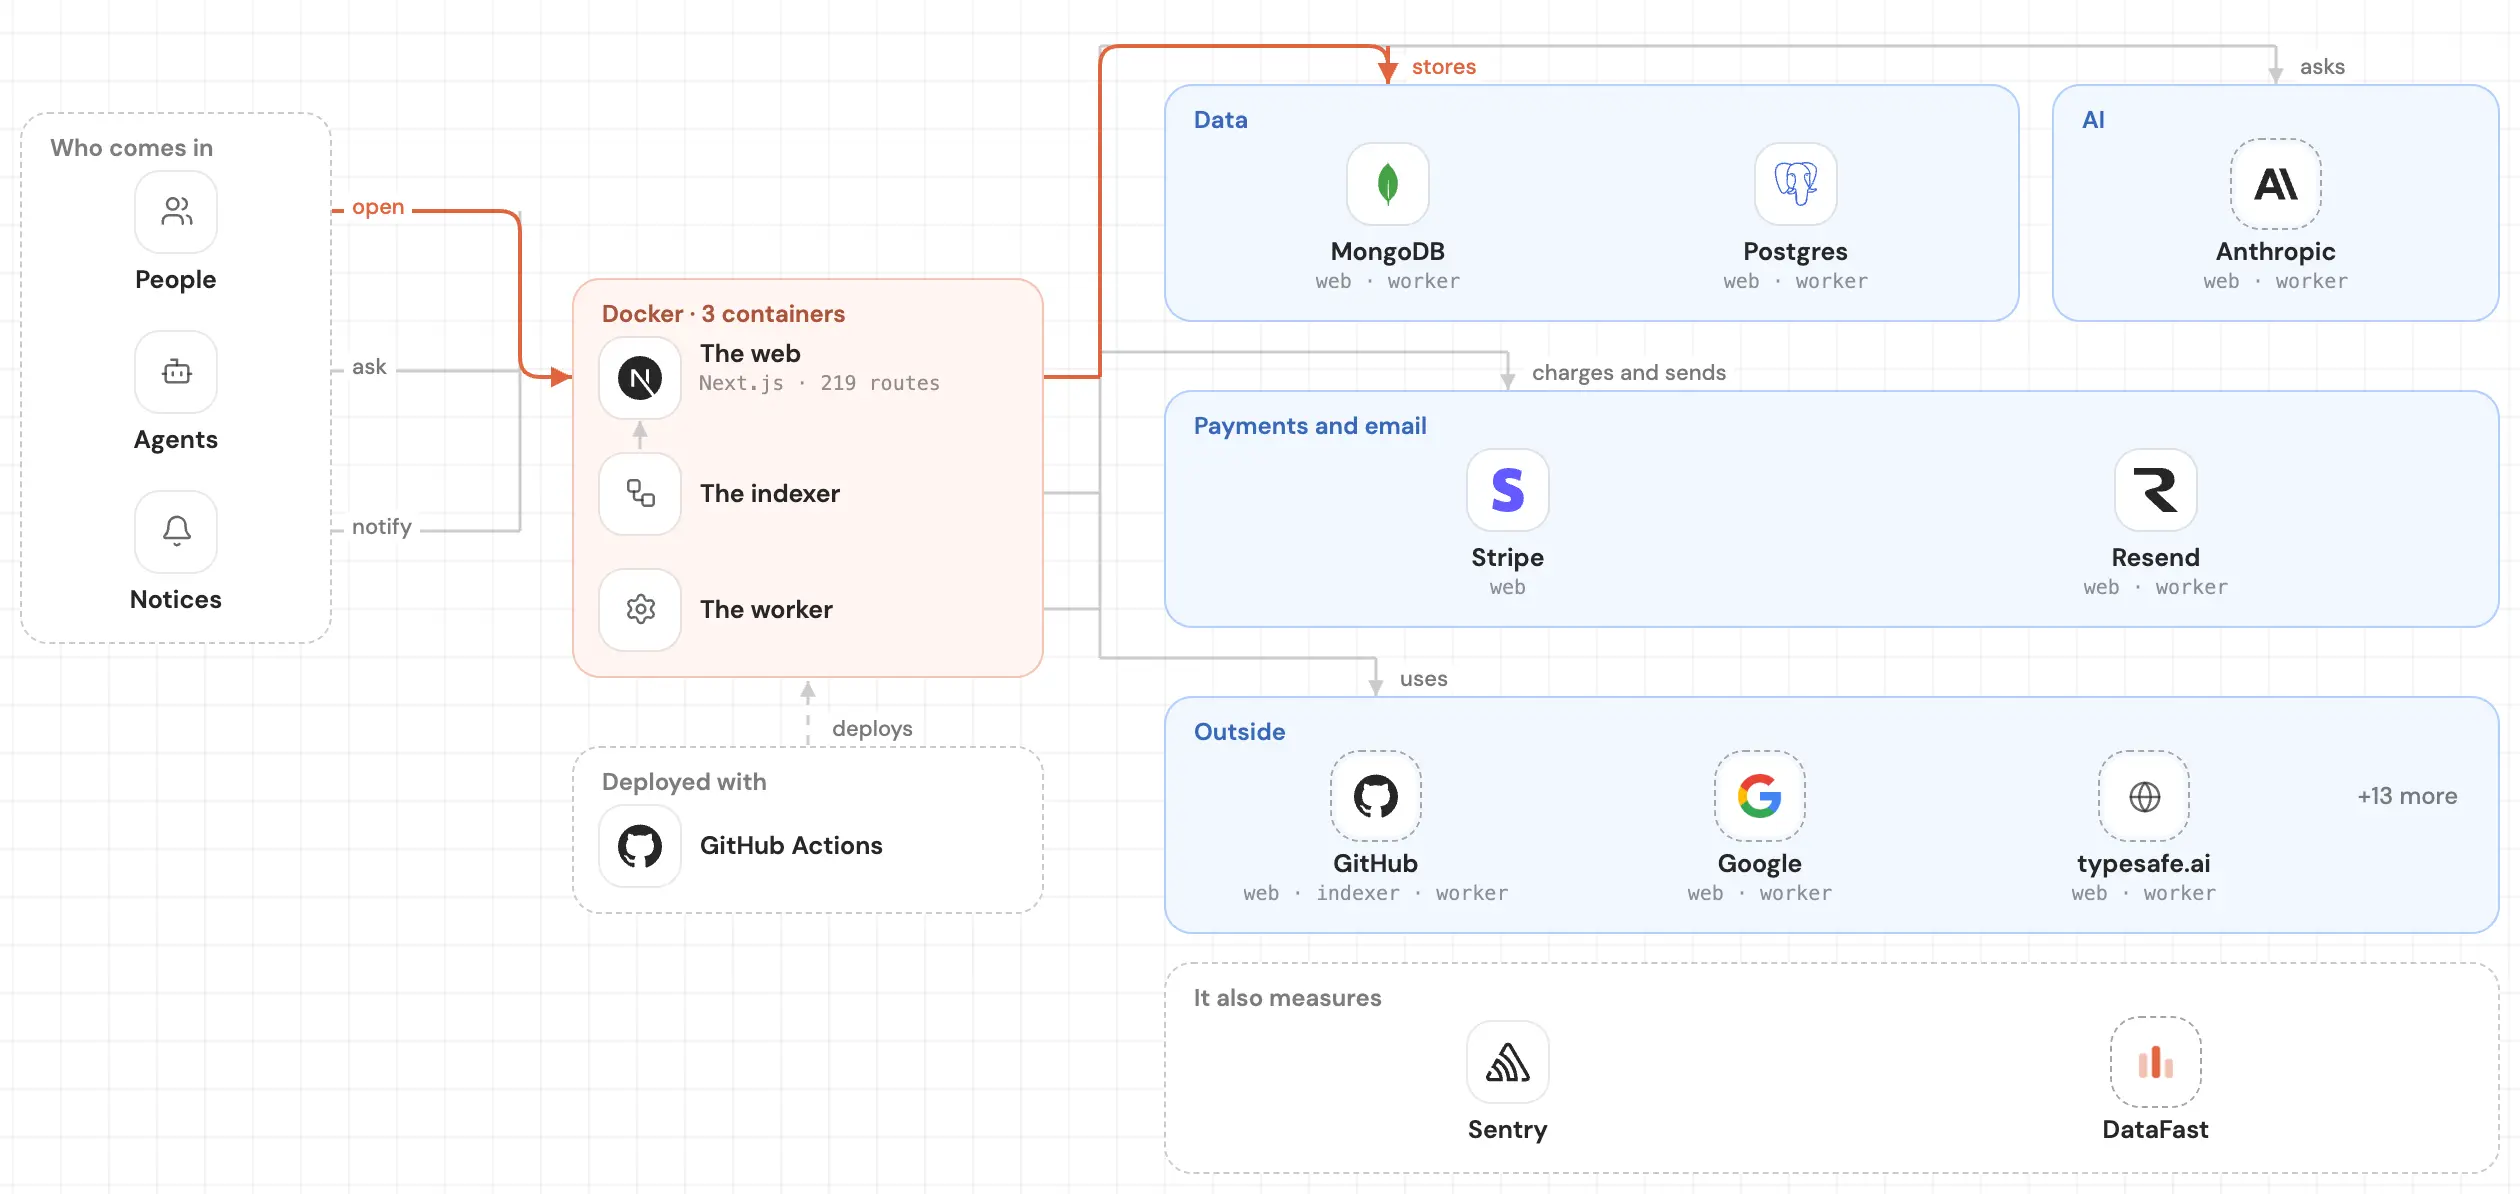
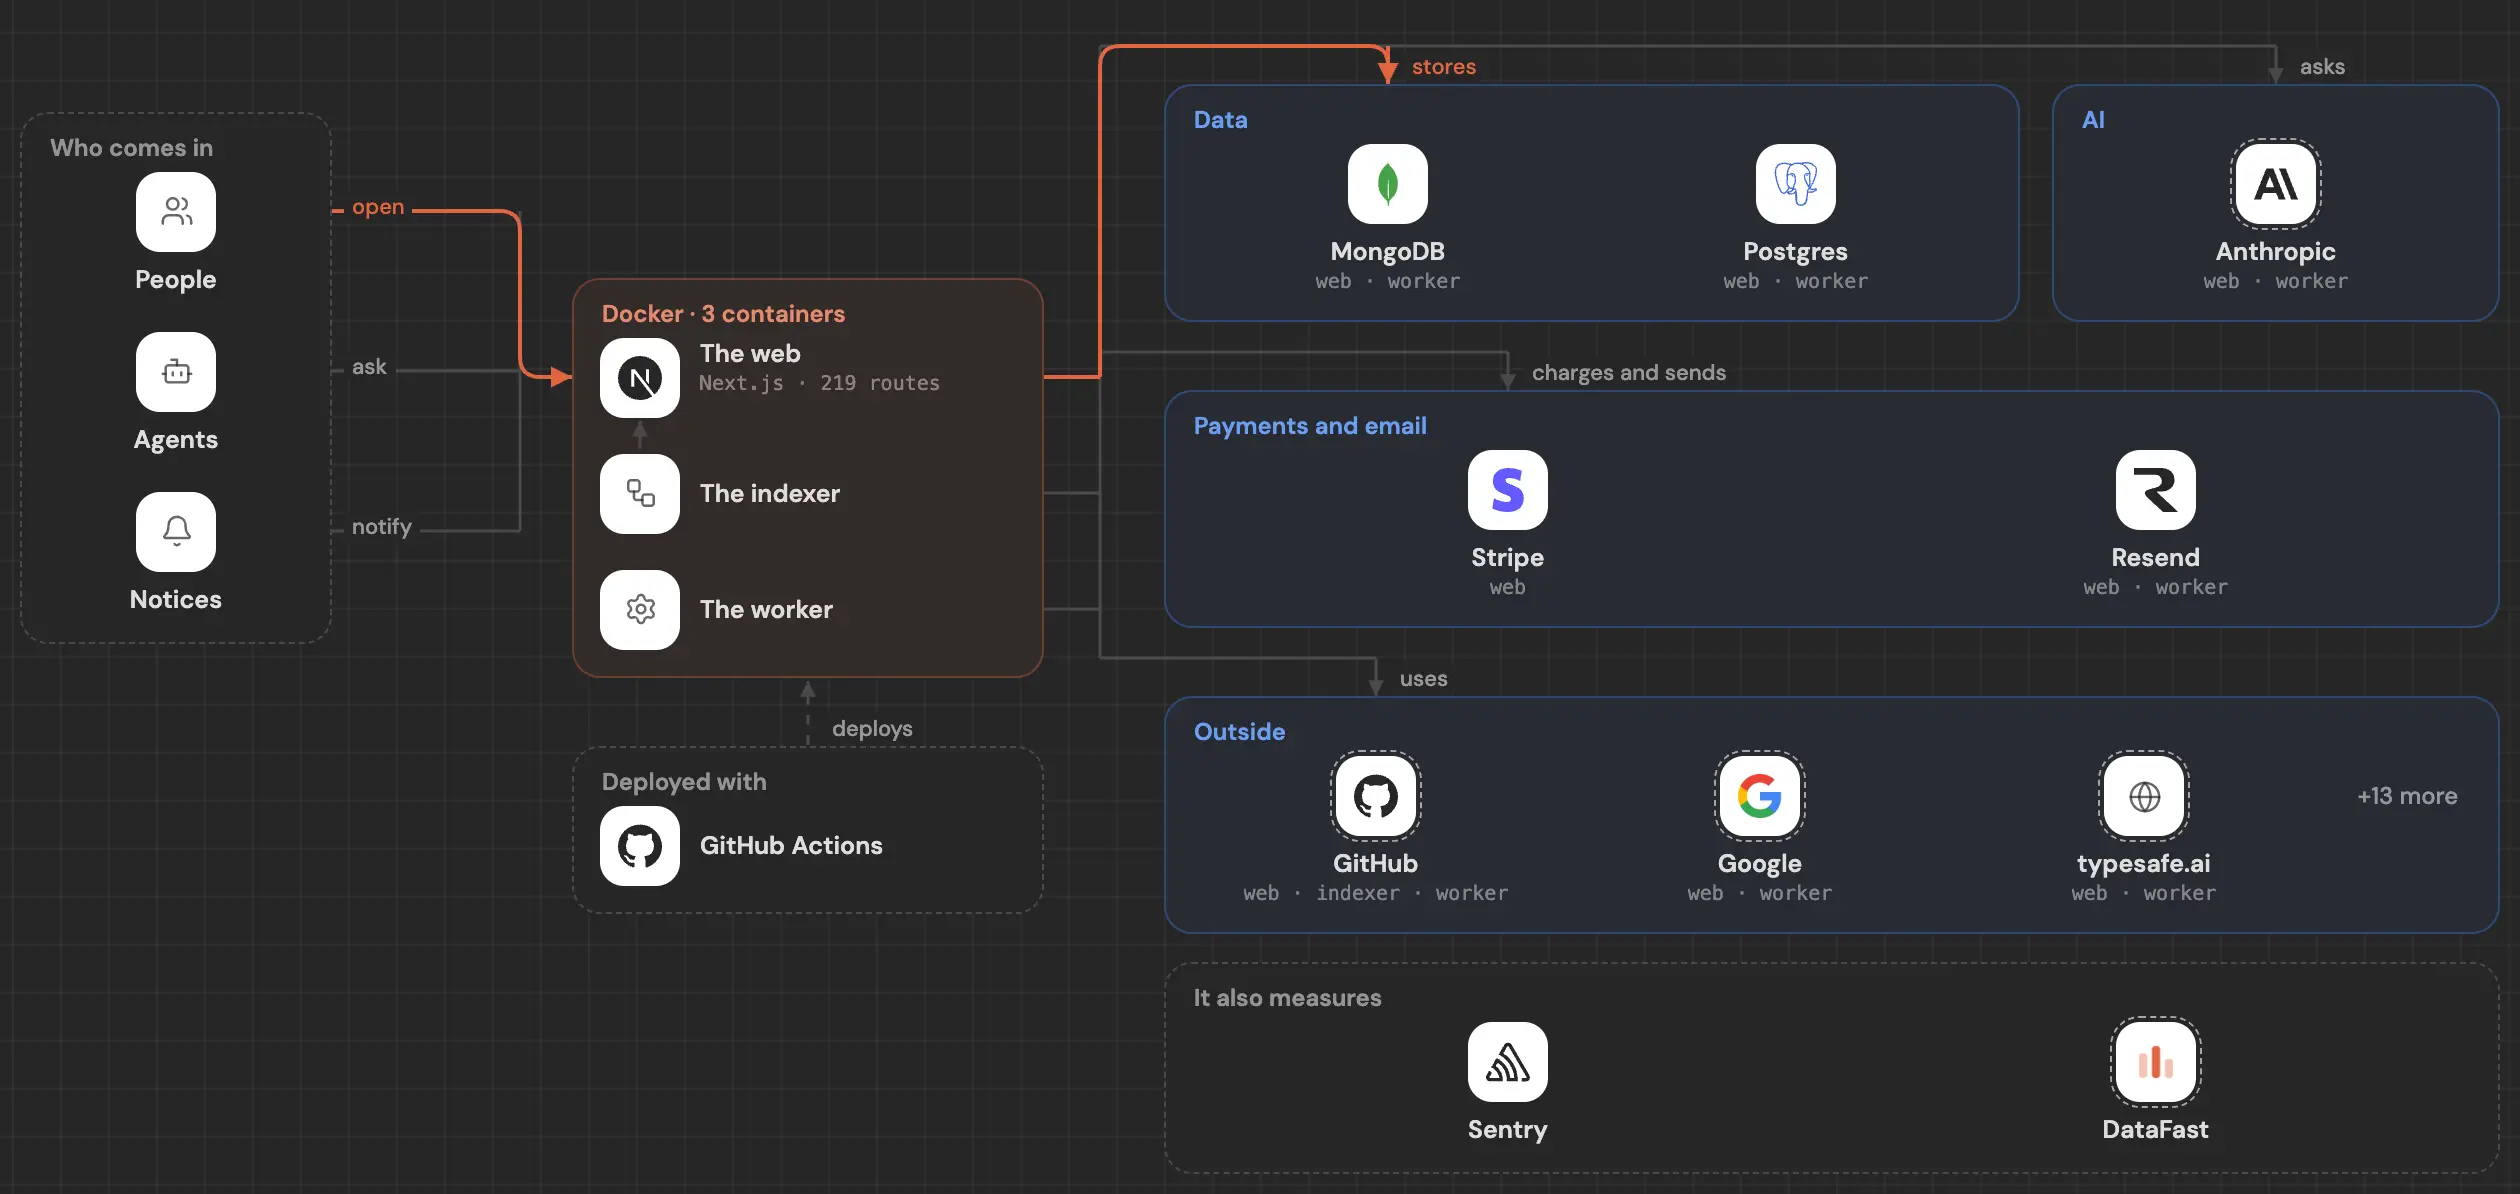
See inside your code, today.
Paste your repo and see it drawn, part by part: a medium one in under a minute.
Free, no account.Private repo? Sign in with GitHub


