What's inside ocrmypdf/
ocrmypdf/OCRmyPDF is a Python repo with 50,888 lines written. SeeRepo read OCRmyPDF and doesn't recognize any of its technologies yet. AI signed 2% of the 4,300 commits of OCRmyPDF.
 LinkedIn
OCRmyPDFPython · MPL-2.0
- lines written
- 50,888
- files
- 94
- test files
- 97
- GitHub stars
- 35,254
Read on November 7, 2026, at commit b457e9e.See each one with its proof
How much of OCRmyPDF did AI write?
Frequently asked questions
What is ocrmypdf/OCRmyPDF?
ocrmypdf/OCRmyPDF is a Python repo with 50,888 lines written. Its description on GitHub: “OCRmyPDF adds an OCR text layer to scanned PDF files, allowing them to be searched”
The proof: its page on GitHub
What is OCRmyPDF built with?
SeeRepo read OCRmyPDF and doesn't recognize any of its technologies yet.
The proof: each service with its file and line
How much of OCRmyPDF did AI write?
AI signed 2% of the 4,300 commits of OCRmyPDF.
The proof: the commits each tool signed
What license does OCRmyPDF have?
OCRmyPDF is released under the MPL-2.0 license.
The proof: its page on GitHub
How many stars does OCRmyPDF have on GitHub?
OCRmyPDF had 35,254 stars on GitHub on November 7, 2026.
The proof: its page on GitHub
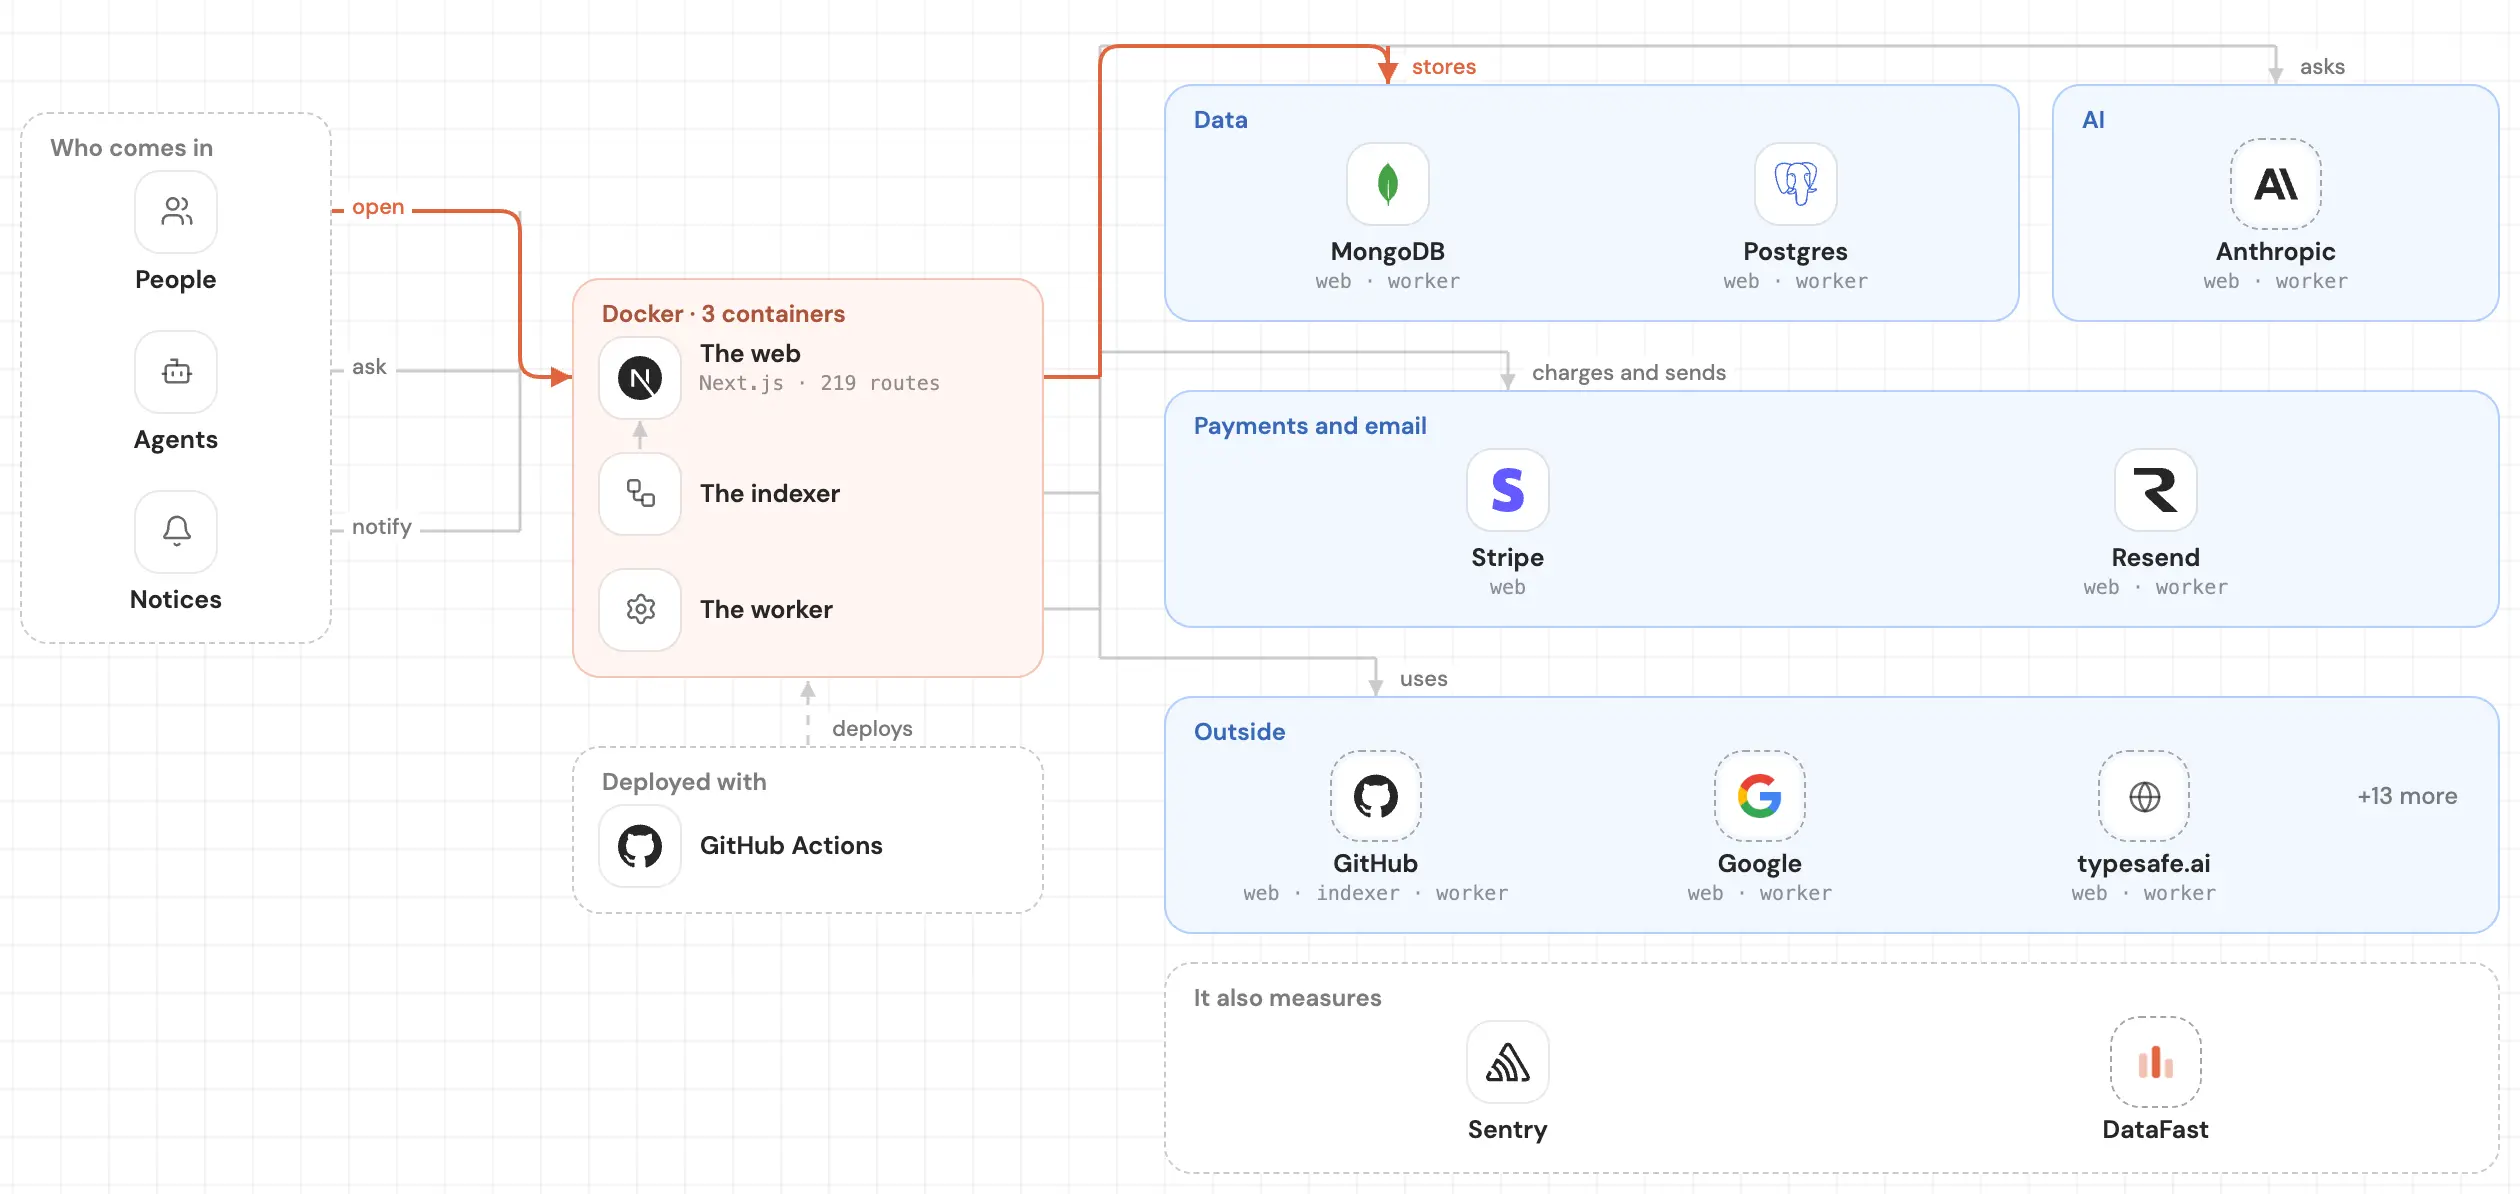
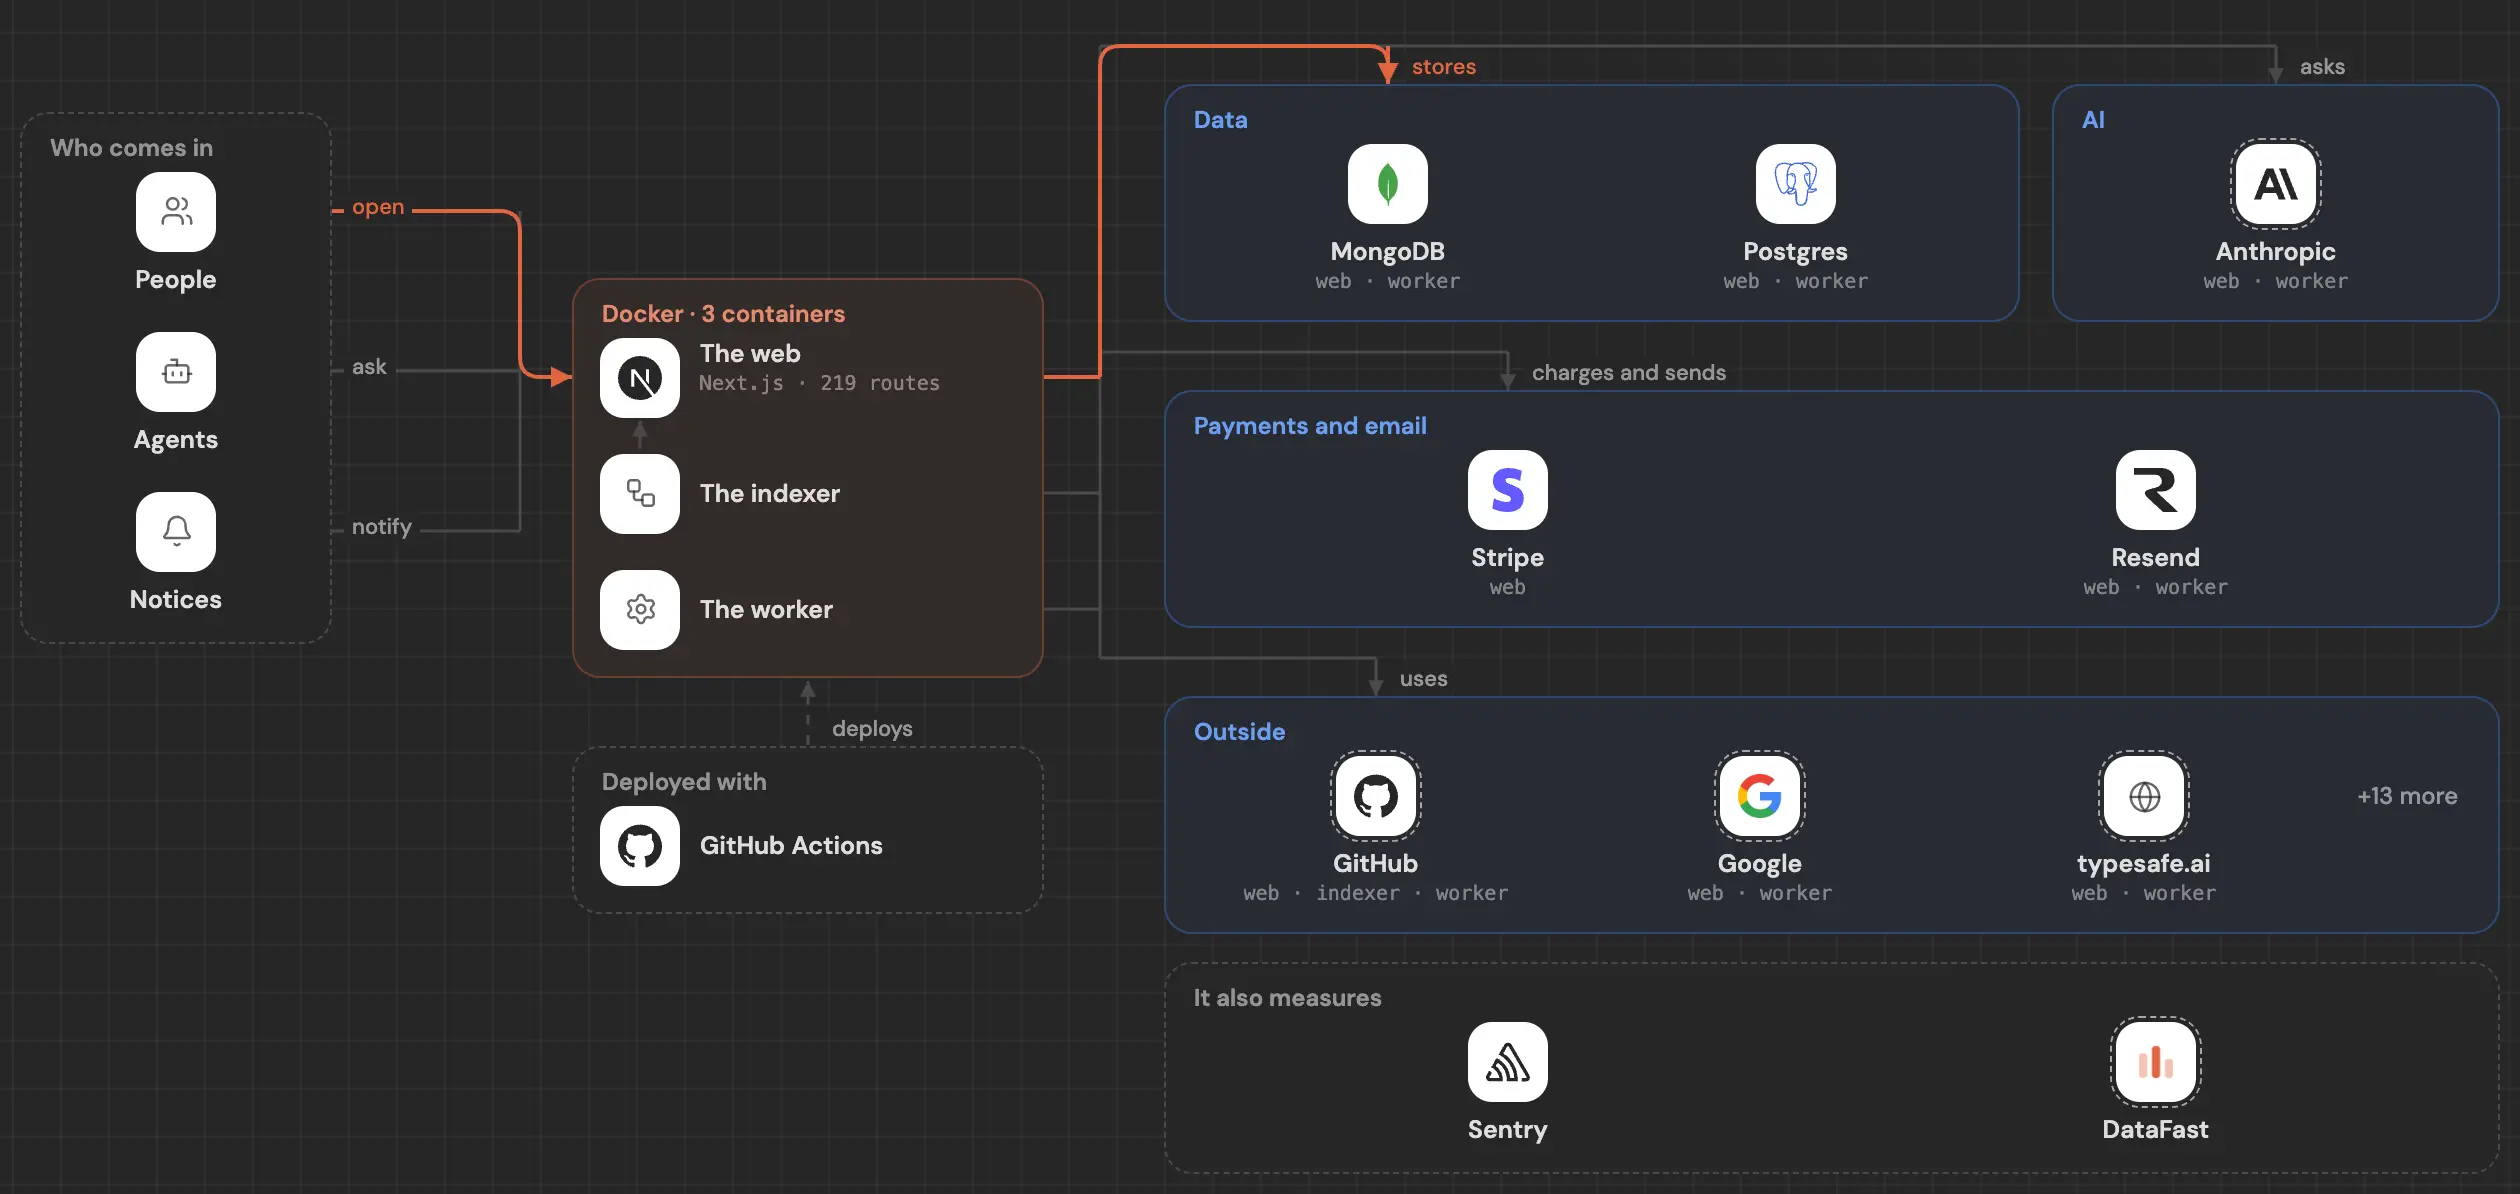
See inside your code, today.
Paste your repo and see it drawn, part by part: a medium one in under a minute.
Free, no account.
Is it your repo? Add its badge, keep it up to date or take it down →


