What is llama_index built with?
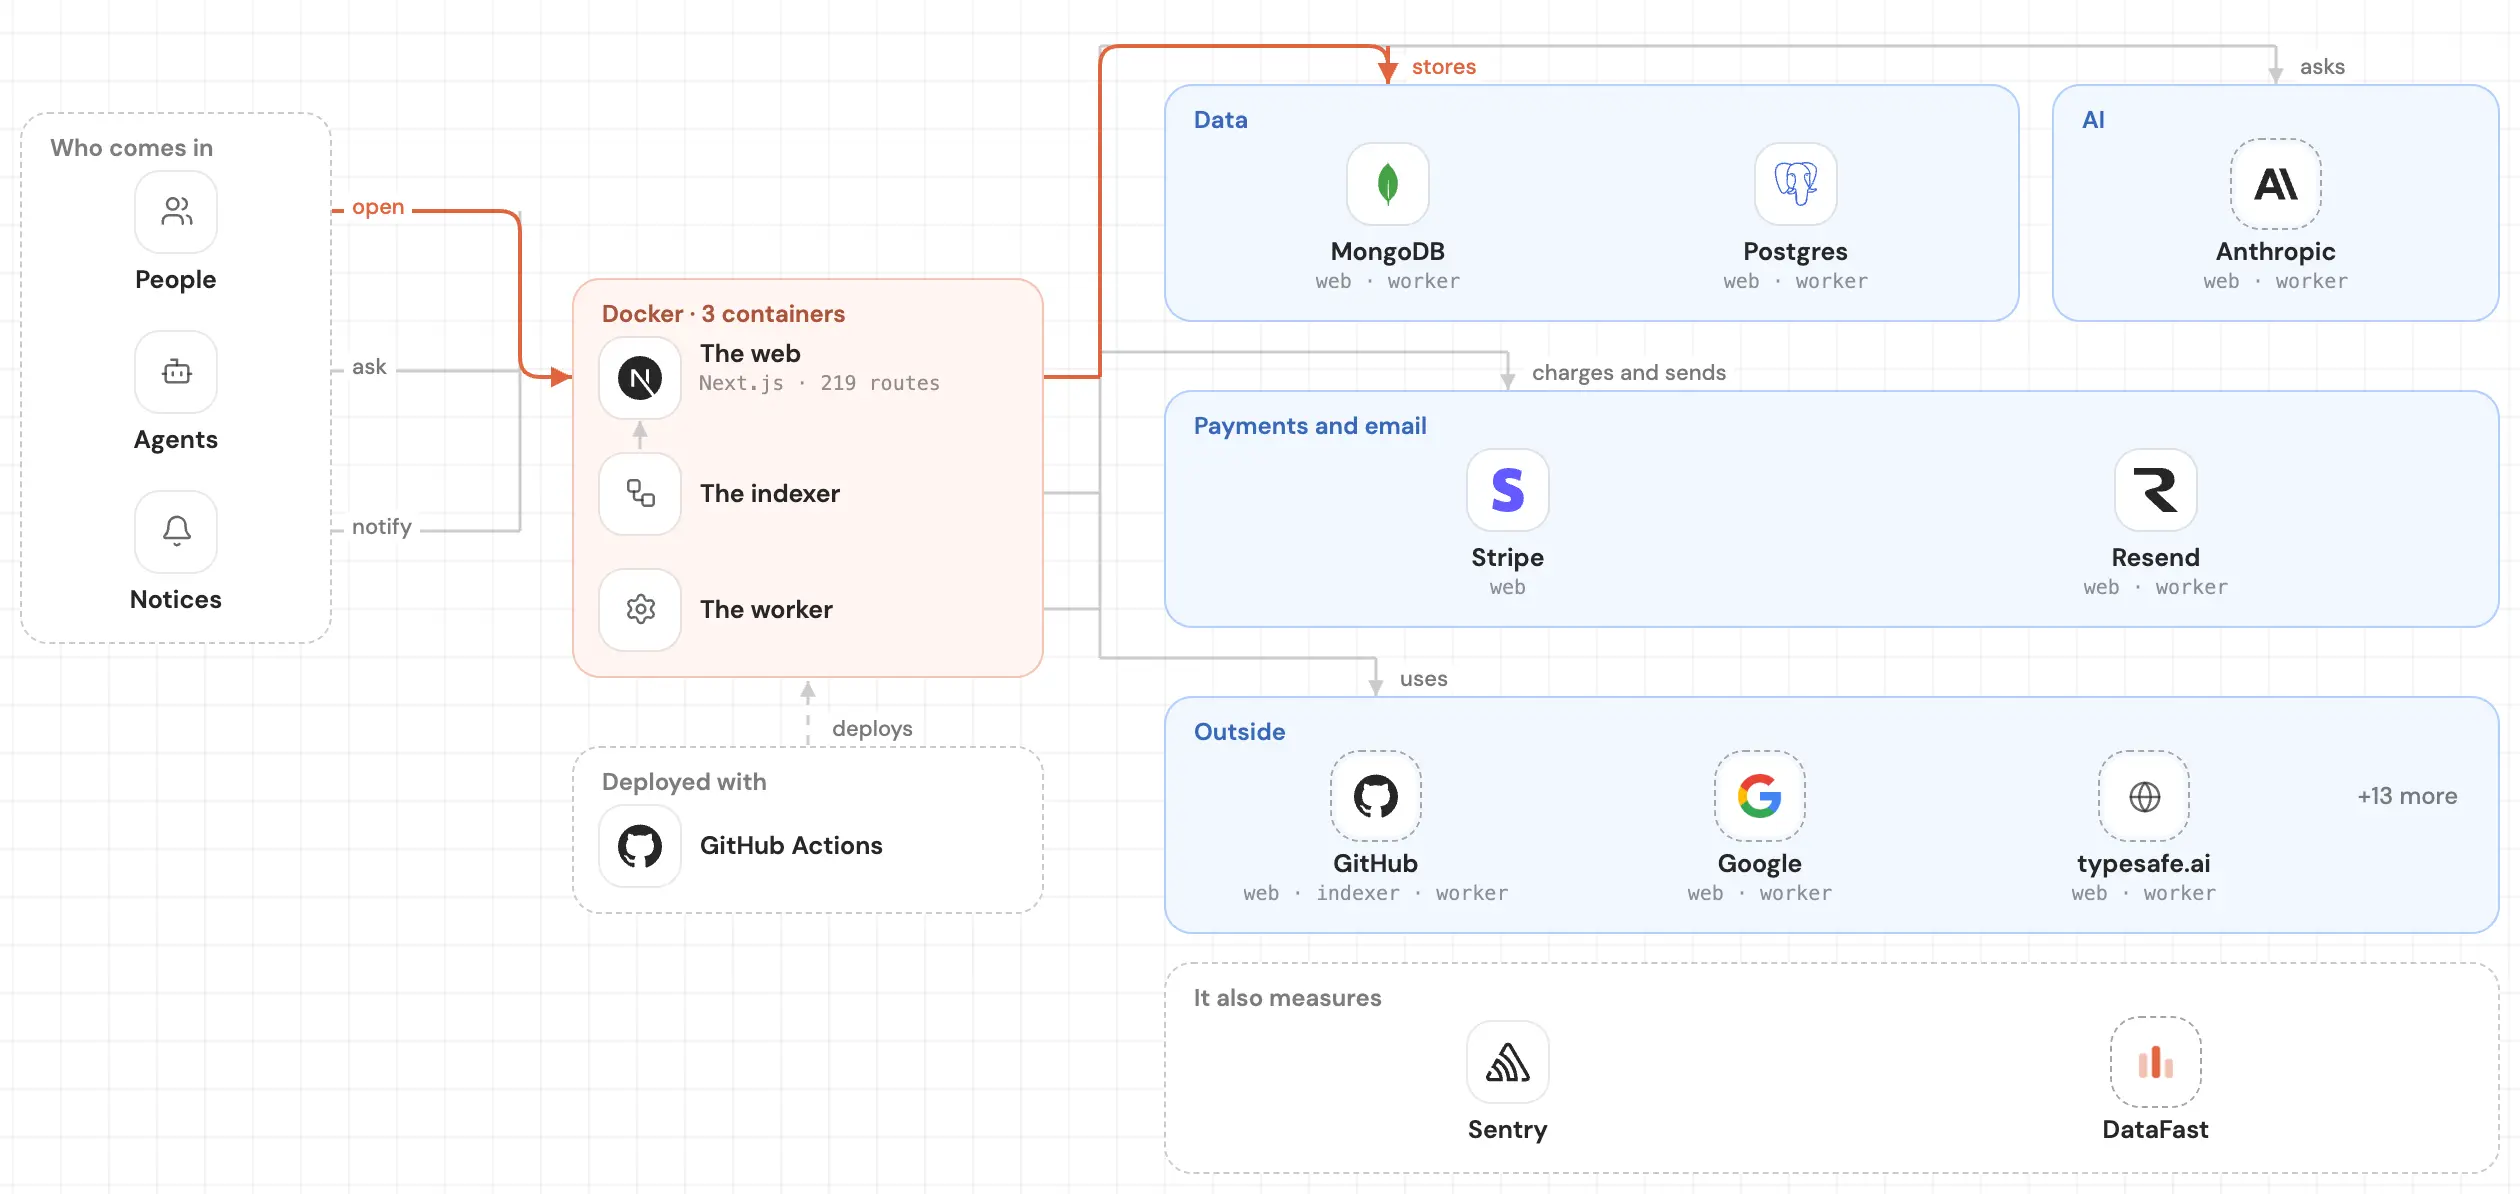
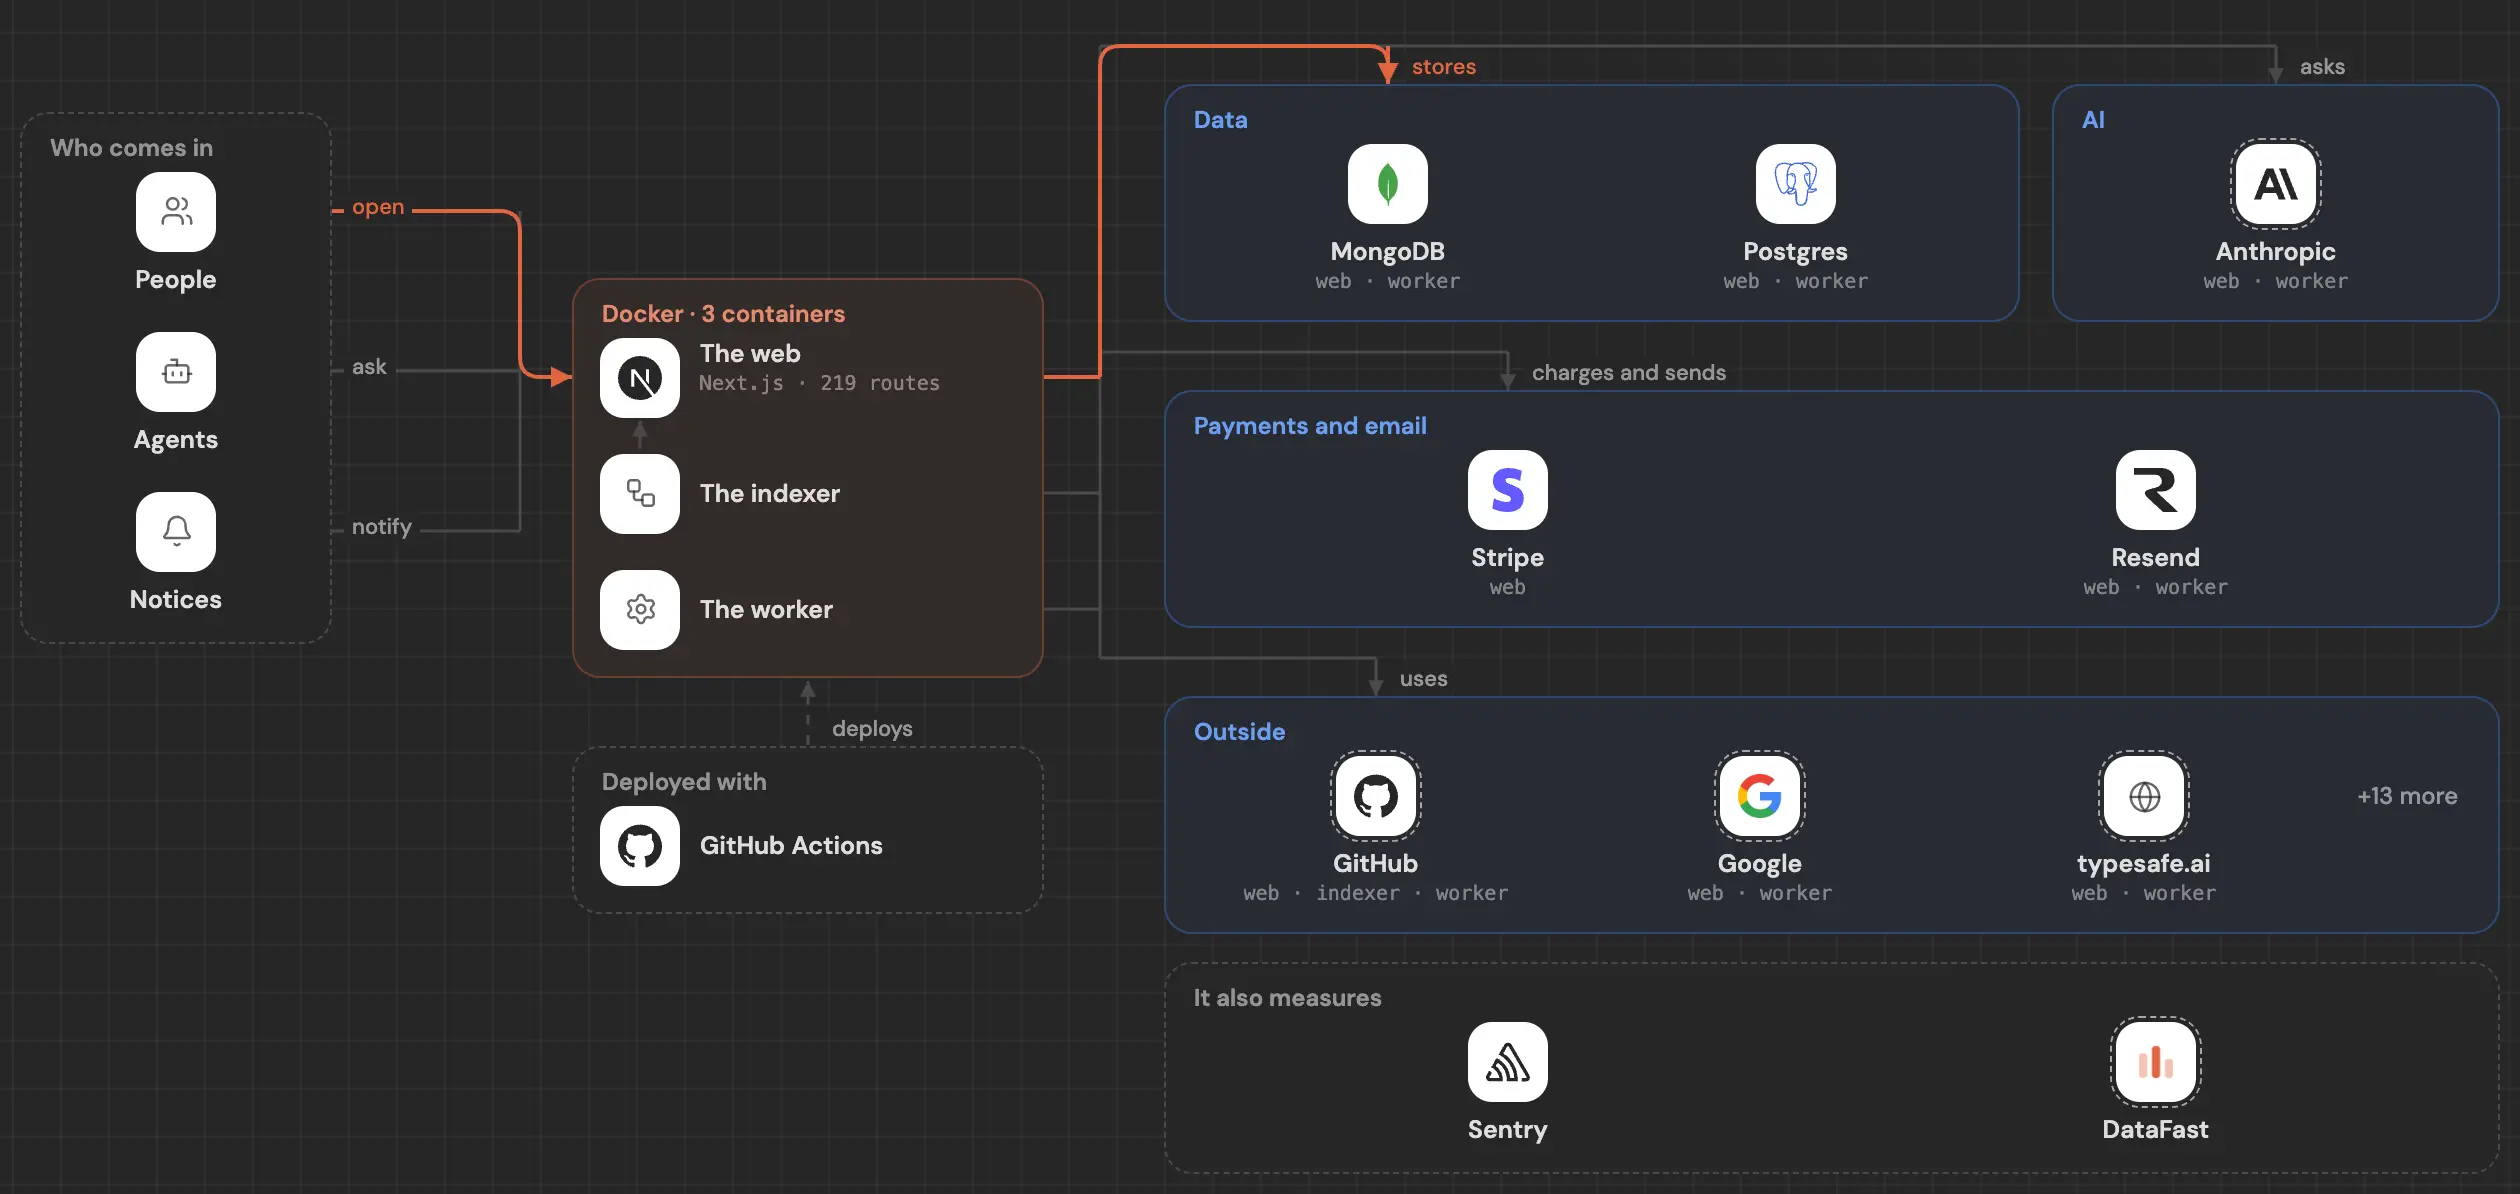
llama_index is a Python repo built with starlette, anyio, graphql-core, tornado, AIOHTTP, and 1 more. It stores its data in pyarrow, lancedb, oracledb, DuckDB, pymilvus, and 6 more, reaches it with SQLAlchemy, signs people in with argon2-cffi, azure-identity, Google, google-auth-httplib2, google-auth-oauthlib, and 3 more, uses AI through einops, firecrawl-py, guardrails-ai, llama-index-core, mem0ai, and 37 more, makes its content with beautifulsoup4, bleach, markupsafe, mistune, nbformat, and 23 more, validates its data with jsonschema-specifications, marshmallow, referencing, rfc3339-validator, Pydantic, and 4 more, is tested with pytest-cov, Pytest, pytest-asyncio, playwright, pytest-mock, and 2 more, deploys with opentelemetry-api, opentelemetry-semantic-conventions, prometheus-client, psutil, python-json-logger, and 4 more, and uses aiomysql, aiosqlite, async-lru, asyncpg, azure-search-documents, and 19 more. It has 473,236 written lines, with 1,607 test files.
 LinkedIn
Read on November 5, 2026, at commit 444fdf0. Read it as markdown
Frontend
Styles 2
- soupsieve
- tinycss2
Interface 5
matplotlib2 files
- Rich2 files
prompt-toolkit
- ipywidgets
- matplotlib-inline
Backend
The base 1
starlette2 files
Data 34
pyarrow5 files
lancedb4 files
oracledb4 files
- DuckDB3 files
- SQLite3 files · llama-index-core/pyproject.toml, line 82
chromadb2 files
falkordb2 files
- MySQL2 files · llama-index-integrations/vector_stores/llama-index-vector-stores-alibabacloud-mysql/pyproject.toml, line 40
pinecone2 files
clickhouse-connect1 file
pyiceberg1 file
pymochow1 file
typesense1 file
pgvector
psycopg
psycopg2-binary
- redis
weaviate-client
- pymilvus3 files
- tablestore3 files
- gcsfs1 file
- pymysql1 file
- pyobvector1 file
- s3fs1 file
- tcvectordb1 file
- aiomysql
- aiosqlite
- async-lru
- asyncpg
- azure-search-documents
- azure-storage-blob
- ibm-db
- pgvecto-rs
- pyzmq
Data access 1
- SQLAlchemy28 files
Sign-in 8
google-auth-oauthlib8 files
- cryptography2 files
- pyjwt2 files
- msal1 file
- argon2-cffi
- azure-identity
AI 42
- torch25 files
cohere5 files
- LangChain5 files
mcp4 files
sentence-transformers4 files
dashscope3 files
fastembed3 files
nltk3 files
litellm2 files
- ModelScope2 files
- Ollama2 files
- scikit-learn2 files
- vLLM2 files
flashrank1 file
langfuse1 file
mlx1 file
nomic1 file
optimum1 file
peft1 file
presidio-analyzer1 file
tokenizers1 file
firecrawl-py
llama-index-core
openai
opencv-python
- PaddlePaddle
- transformers23 files
- ibm-watsonx-ai6 files
- tiktoken5 files
- flagembedding3 files
- sentencepiece3 files
- openvino2 files
- tritonclient2 files
- datasets1 file
- exa-py1 file
- hnswlib1 file
- mlx-lm1 file
- paddleocr1 file
- einops
- guardrails-ai
- mem0ai
- tavily-python
Services 1
Support
Content 28
pillow22 files
unstructured6 files
- jinja24 files
lxml4 files
pymupdf4 files
docling1 file
pypdf1 file
pypdf21 file
tinytag1 file
markupsafe
- bs417 files
- html2text6 files
- defusedxml4 files
- filetype3 files
- docx2txt2 files
- markdownify2 files
- lxml-html-clean1 file
- markitdown1 file
- nbconvert1 file
- pdf2image1 file
- pdfplumber1 file
- youtube-transcript-api1 file
- beautifulsoup4
- bleach
- mistune
- nbformat
- newspaper3k
- xlrd
Validation 9
- Pydantic70 files
docling-core2 files
- pydantic-core1 file
marshmallow
- annotated-types1 file
- jsonschema1 file
- jsonschema-specifications
- referencing
- rfc3339-validator
Testing 7
- Pytest474 files
pytest-asyncio53 files
playwright7 files
pytest-mock6 files
- Faker2 files
- Selenium2 files
pytest-cov
Deploy 9
- docker7 files
- Alibaba Cloud6 files
- OpenTelemetry2 files
- opentelemetry-api
opentelemetry-semantic-conventions
prometheus-client
psutil
- boto316 files
- python-json-logger
Tools 45
click9 files
ipython3 files
- Setuptools1 file
- Black
boto3-stubs
coverage
griffe
ipykernel
jedi
- Jupyter
jupyterlab
notebook
parso
- pre-commit
pygments
pylint
- Ruff
virtualenv
- typing-extensions39 files
- packaging8 files
- astroid
- asttokens
- cfgv
- codespell
- distlib
- executing
- identify
- iniconfig
- mccabe
- mypy
- mypy-extensions
- nbclient
- nodeenv
- overrides
- pathspec
- pip
- pluggy
- pure-eval
- pycparser
- stack-data
- types-protobuf
- types-python-dateutil
- types-pyyaml
- types-requests
- types-setuptools
Other 84
fsspec36 files
- NumPy36 files
- pandas25 files
- tqdm14 files
dataclasses-json9 files
pyyaml6 files
websockets3 files
networkx2 files
geopy1 file
platformdirs1 file
- Polars1 file
praw1 file
python-dateutil1 file
slack-sdk1 file
termcolor1 file
trafilatura1 file
tweepy1 file
urllib31 file
wandb1 file
wrapt1 file
attrs
- Babel
certifi
filelock
joblib
python-gitlab
- requests123 files
- httpx53 files
- tenacity32 files
- deprecated18 files
- nest-asyncio5 files
- arxiv3 files
- pyaudio2 files
- tomli2 files
- wikipedia2 files
- yfinance2 files
- dirtyjson1 file
- duckduckgo-search1 file
- grpcio1 file
- more-itertools1 file
- python-dotenv1 file
- retrying1 file
- six1 file
- yarl1 file
- ag-ui-protocol
- aiohappyeyeballs
- aiohttp-retry
- aiosignal
- arrow
- async-timeout
- cffi
- chardet
- charset-normalizer
- colorama
- comm
- decorator
- dill
- exceptiongroup
- frozenlist
- greenlet
- h11
- httpcore
- idna
- importlib-metadata
- json5
- jsonpointer
- multidict
- pexpect
- propcache
- ptyprocess
- pywin32
- regex
- requests-toolbelt
- rpds-py
- sniffio
- sseclient-py
- tomlkit
- traitlets
- typing-inspection
- wcwidth
- webcolors
- websocket-client
- zipp
Other repos with a similar stack
Ordered by how much of its stack they share with llama_index, then by stars.
- bojieliai-agent-book57.2k
《深入理解 AI Agent:设计原理与工程实践》(李博杰 著)开源主仓库:全书正文、编译版 PDF 与按章配套代码
40 of 281 in commonCompare → - open-webuiopen-webui157.7k
User-friendly AI Interface (Supports Ollama, OpenAI API, ...)
28 of 281 in common · SvelteCompare →
Frequently asked questions
What language is llama_index written in?
What framework does llama_index use?
What database does llama_index use?
What does llama_index sign people in with?
Does llama_index use AI?
What services does llama_index use?
Does llama_index have tests?
Which repos have a stack like llama_index's?
See inside your code, today.
Paste your repo and see it drawn, part by part: a medium one in under a minute.
Free, no account.
Is it your repo? Add its badge, keep it up to date or take it down →


