Memori vs llama_index
Memori and llama_index share 8 technologies: AIOHTTP, SQLite, ipywidgets, OpenAI, sentence-transformers, tiktoken, tokenizers, and fastembed. Both are written in Python.
 LinkedIn
What they share and what sets them apart
Memori
Memori is agent-native memory infrastructure. A LLM-agnostic layer that turns agent execution and conversation into structured, persistent state for production systems. Built for enterprise, Memori works with the data infrastructure you already run, no rip-and-replace, and deploys across managed cloud, single-tenant cloud, VPC, and on-premises.
Python17.4kRead on November 7, 2026, at commit 574b1eaWhat is Memori built with?Only in Memori
In common
- AIOHTTP
- SQLite
- ipywidgets
 OpenAI
sentence-transformers
- tiktoken
tokenizers
- fastembed
llama_index
LlamaIndex is the document processing platform for AI
Python52.8kRead on November 5, 2026, at commit 444fdf0What is llama_index built with?Only in llama_index
starlette
- aiomysql
- aiosqlite
- async-lru
- asyncpg
- azure-search-documents
- azure-storage-blob
- ibm-db
- pgvecto-rs
pgvector
psycopg
psycopg2-binary
- pyzmq
- Redis
weaviate-client
pyarrow
lancedb
oracledb
- DuckDB
- pymilvus
- tablestore
chromadb
falkordb
- MySQL
pinecone
clickhouse-connect
- gcsfs
pyiceberg
pymochow
- pymysql
- pyobvector
- s3fs
- tcvectordb
typesense
- ElevenLabs
- anyio
- graphql-core
tornado
- Ray
- soupsieve
- tinycss2
- matplotlib-inline
prompt-toolkit
matplotlib
- Rich
- SQLAlchemy
- argon2-cffi
- azure-identity
google-auth-httplib2
- cryptography
- pyjwt
- msal
- einops
firecrawl-py
- guardrails-ai
llama-index-core
- mem0ai
opencv-python
- PaddlePaddle
- tavily-python
- torch
- transformers
- ibm-watsonx-ai
cohere
- LangChain
- MCP
dashscope
- flagembedding
nltk
- sentencepiece
litellm
- ModelScope
- Ollama
- openvino
- scikit-learn
- tritonclient
- vLLM
- datasets
- exa-py
- flashrank
- hnswlib
langfuse
mlx
- mlx-lm
nomic
optimum
- paddleocr
peft
presidio-analyzer
- beautifulsoup4
- bleach
markupsafe
mistune
- nbformat
- newspaper3k
- xlrd
pillow
- bs4
- html2text
unstructured
- defusedxml
- jinja2
lxml
pymupdf
- filetype
- docx2txt
- markdownify
docling
- lxml-html-clean
- markitdown
- nbconvert
- pdf2image
- pdfplumber
pypdf
pypdf2
tinytag
- youtube-transcript-api
- jsonschema-specifications
marshmallow
- referencing
- rfc3339-validator
- Pydantic
docling-core
- annotated-types
- jsonschema
- pydantic-core
- opentelemetry-api
opentelemetry-semantic-conventions
prometheus-client
psutil
- python-json-logger
- boto3
- docker
- Alibaba Cloud
- OpenTelemetry
Side by side
Frequently asked questions
Which is bigger, Memori or llama_index?
Which has more GitHub stars, Memori or llama_index?
The proof: run-llama/llama_index on GitHub
Which has more tests, Memori or llama_index?
Which was updated more recently, Memori or llama_index?
The proof: run-llama/llama_index's commits on GitHub
Which has more commits signed by AI, Memori or llama_index?
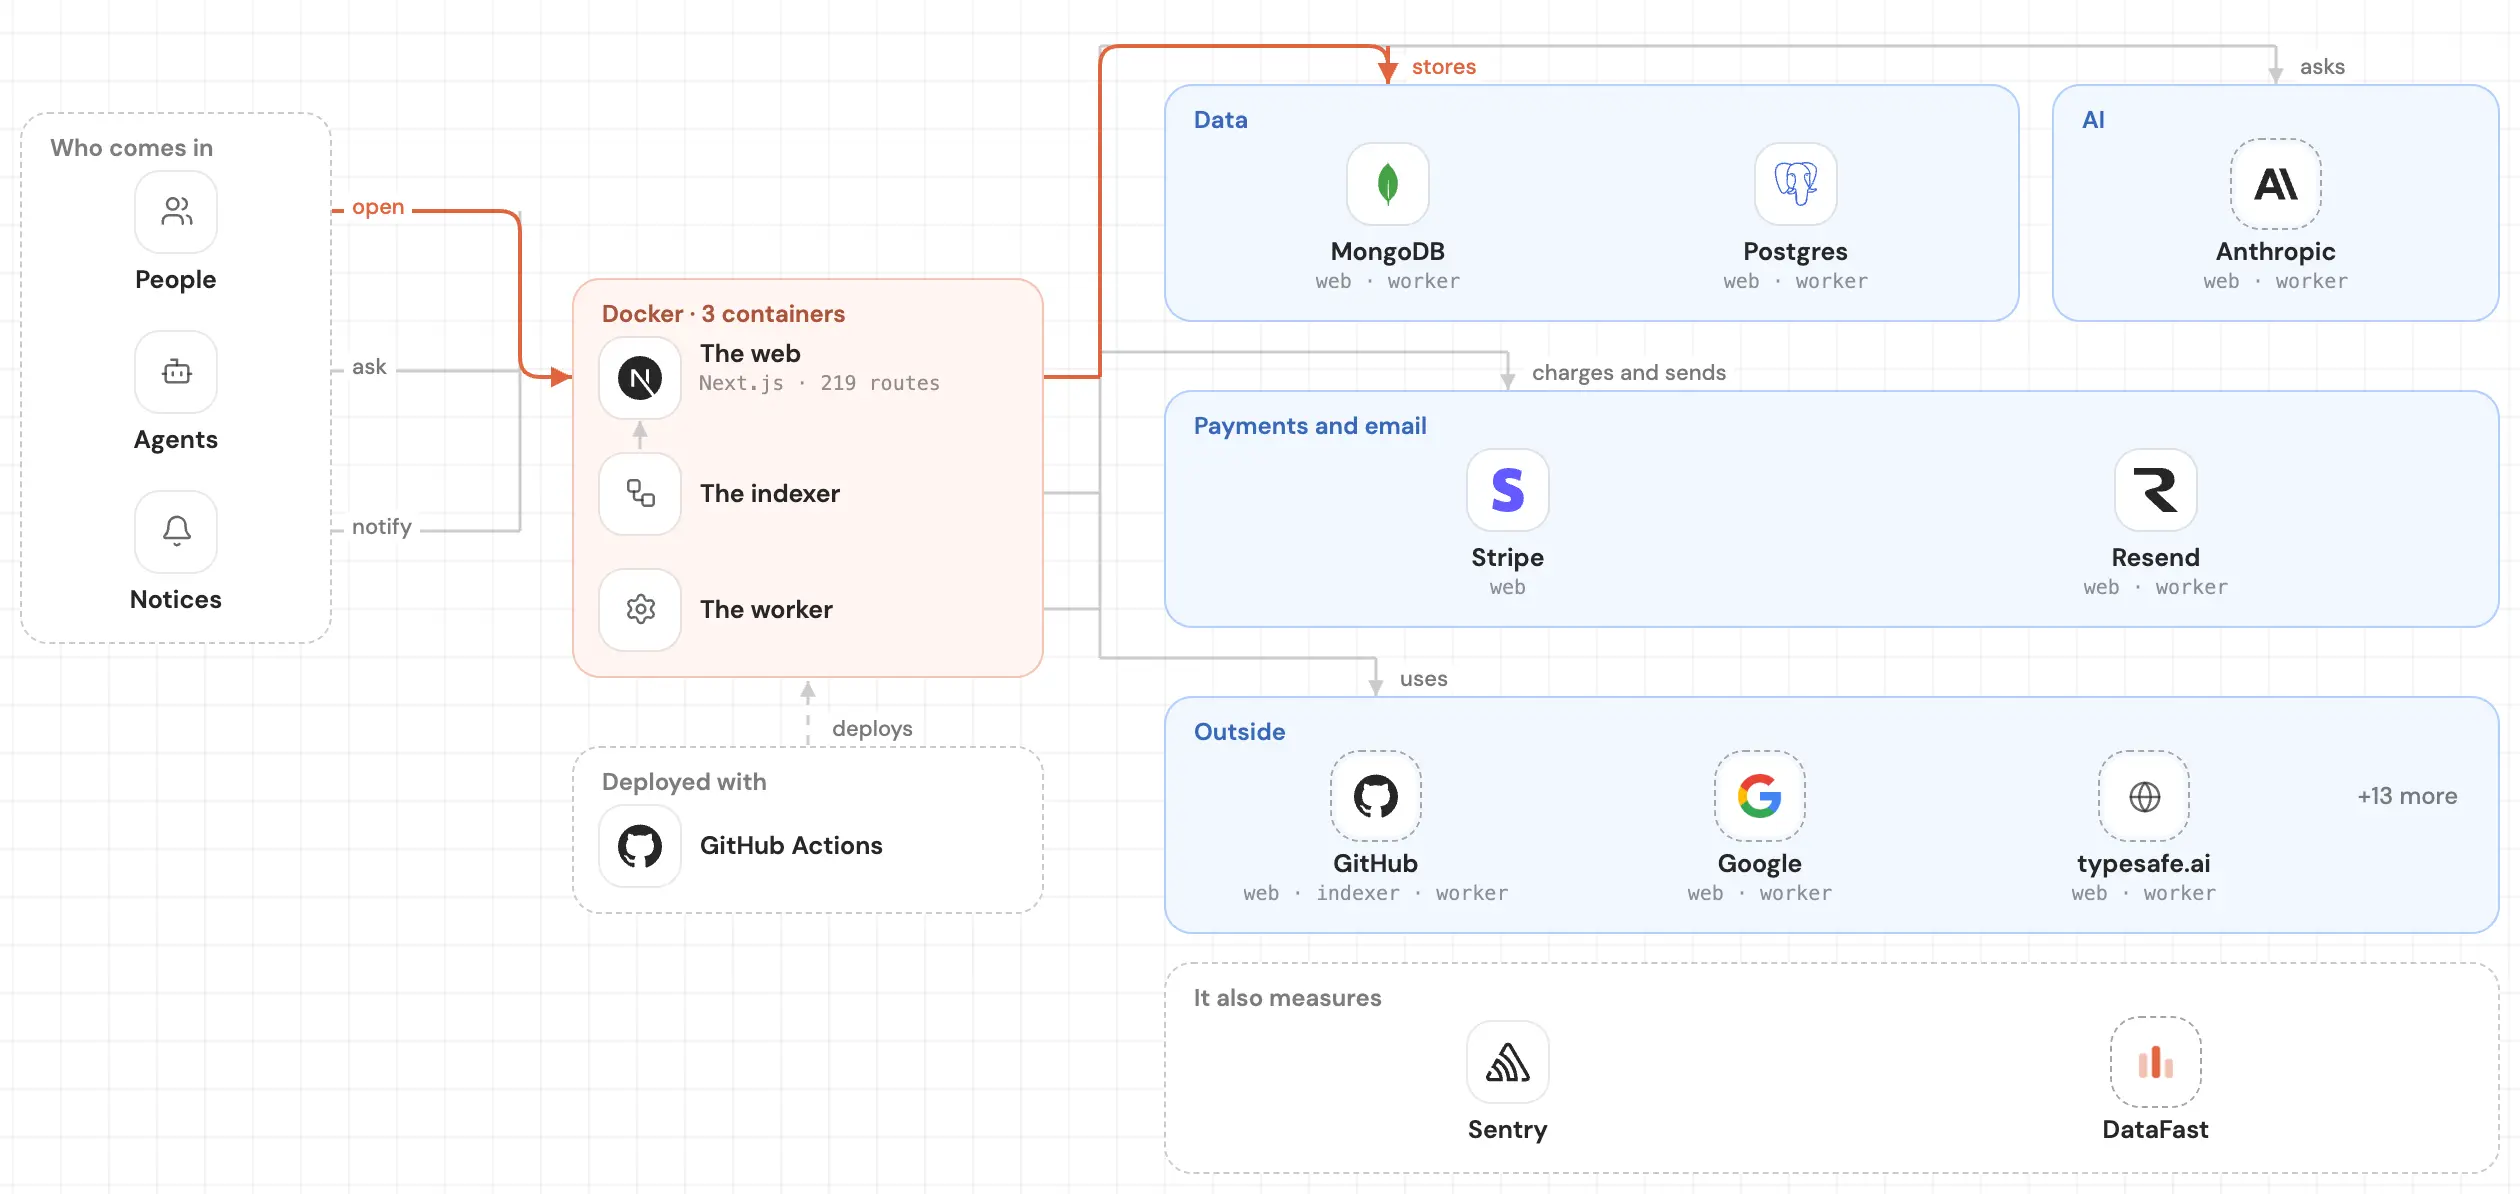
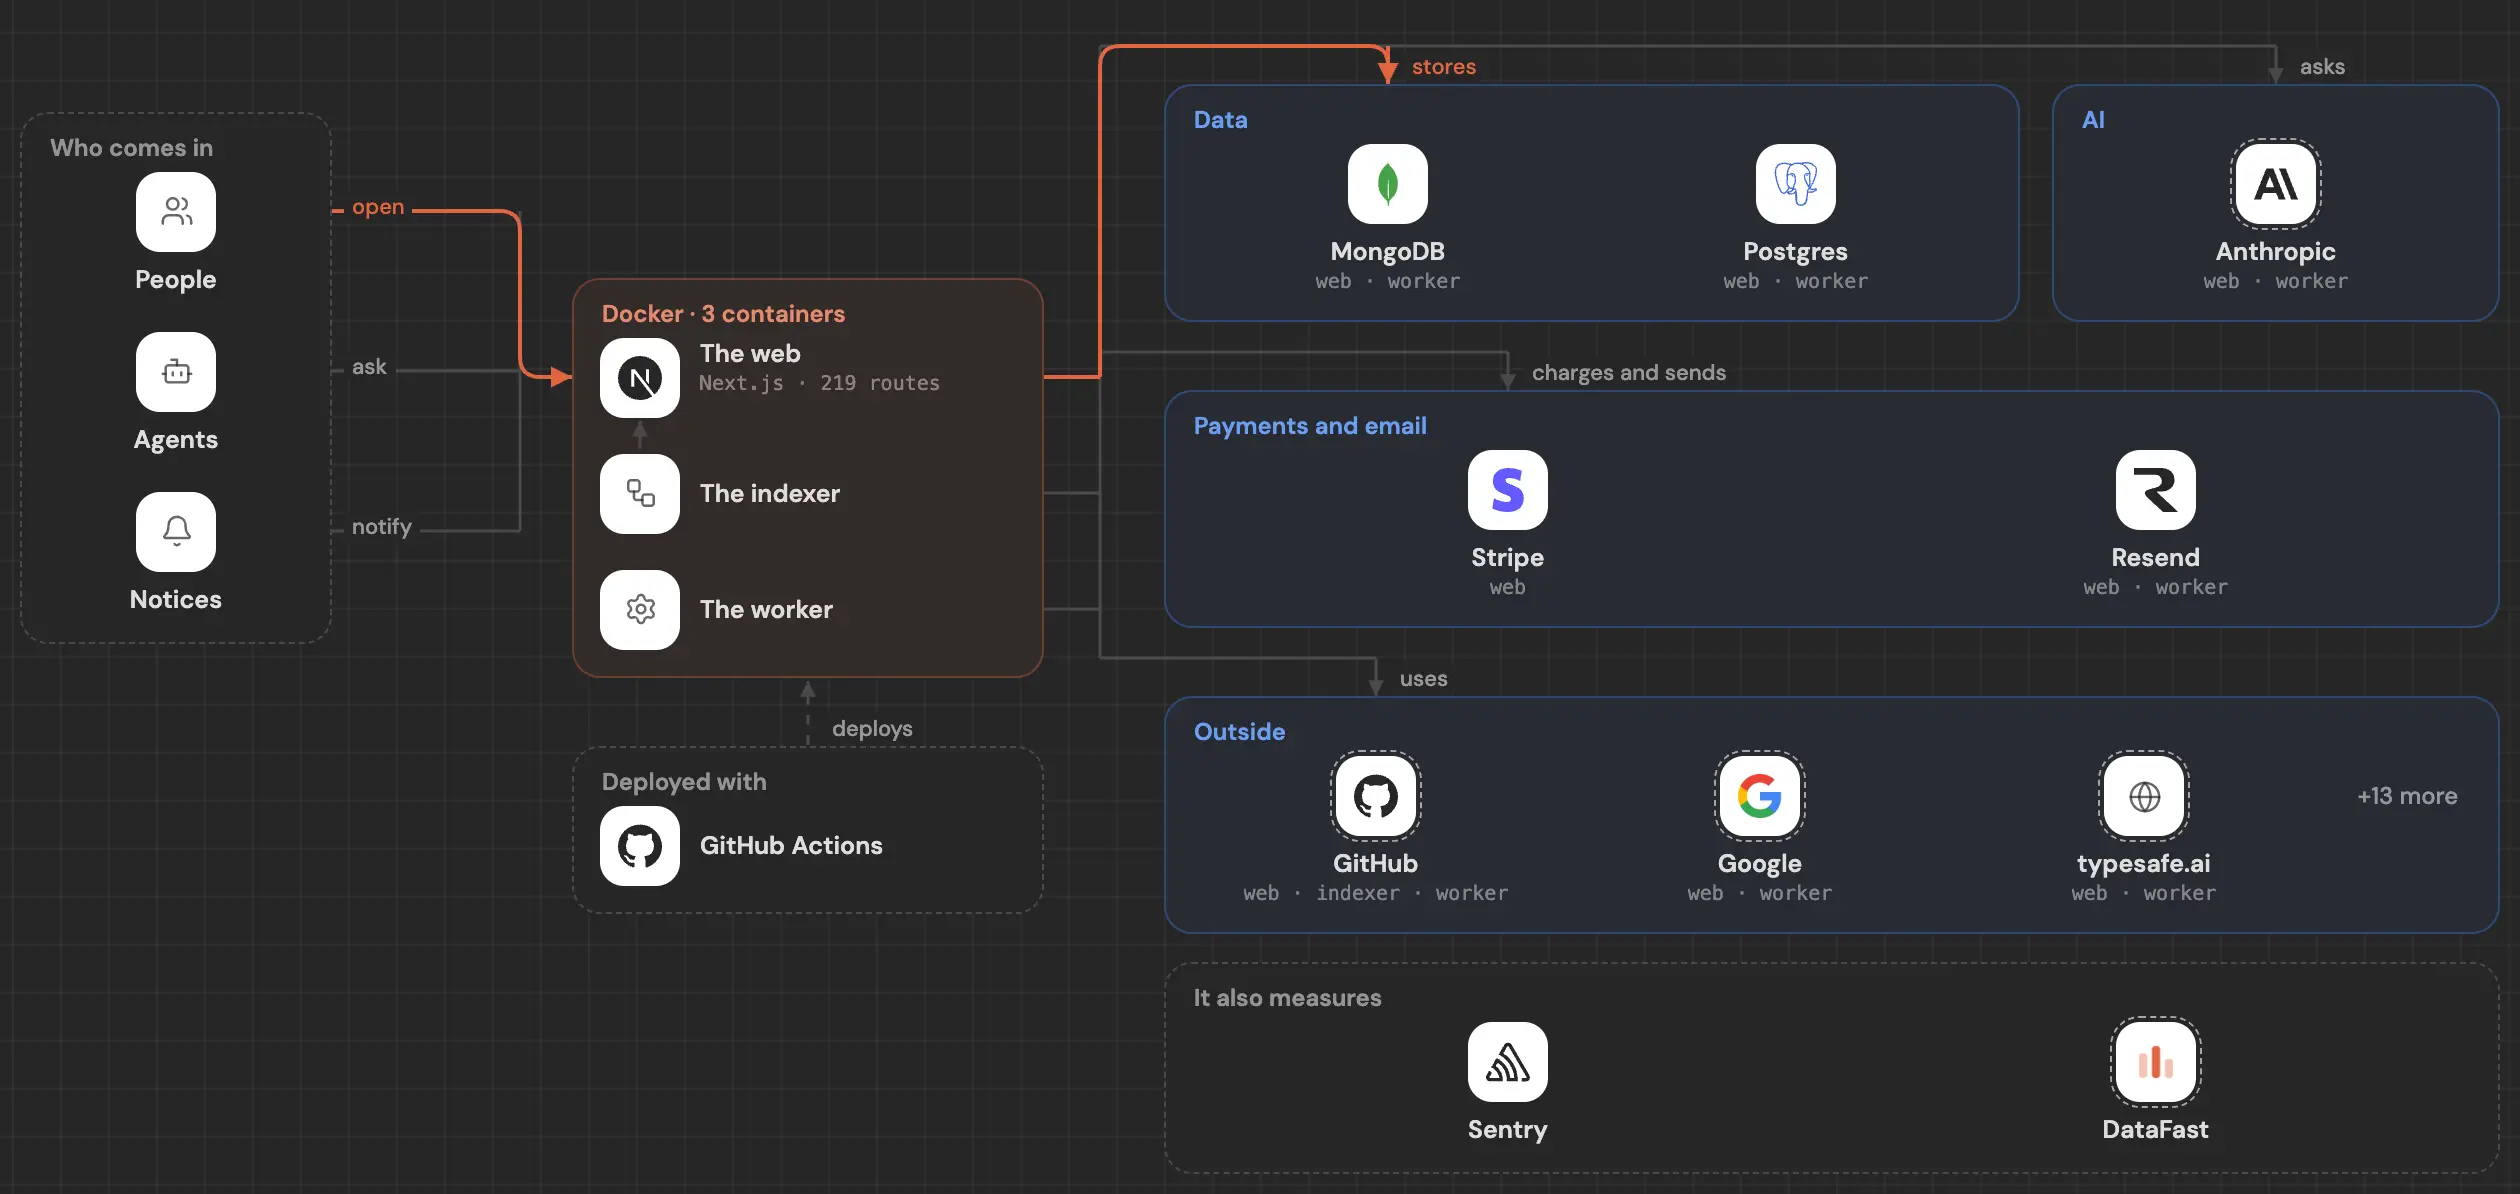
See inside your code, today.
Paste your repo and see it drawn, part by part: a medium one in under a minute.
Free, no account.


