llama_index vs MemoryBear
llama_index and MemoryBear share 53 technologies: starlette, asyncpg, oss2, psycopg, psycopg2-binary, Redis, Neo4j, anyio, AIOHTTP, soupsieve, prompt-toolkit, matplotlib, Rich, SQLAlchemy, cryptography, pyjwt, OpenAI, opencv-python, LangChain, tiktoken, MCP, dashscope, nltk, chonkie, ModelScope, Ollama, scikit-learn, langfuse, beautifulsoup4, markupsafe, webencodings, xlrd, pillow, jinja2, lxml, pymupdf, markdownify, olefile, pdfplumber, pypdf, pypdf2, tika, jsonschema-specifications, marshmallow, referencing, Pydantic, annotated-types, jsonschema, opentelemetry-semantic-conventions, prometheus-client, psutil, boto3, and OpenTelemetry. Both are written in Python.
 LinkedIn
What they share and what sets them apart
llama_index
LlamaIndex is the document processing platform for AI
Python52.9kRead on November 13, 2026, at commit baeabbfWhat is llama_index built with?Only in llama_index
- aiomysql
- aiosqlite
- async-lru
- azure-cosmos
- azure-data-tables
- azure-search-documents
- azure-storage-blob
- ibm-db
- nebula3-python
pgml
- pgvecto-rs
- pgvector
pickleshare
pyathena
- pydrive
- pylance
- pymongo
python-arango
pyvespa
- pyzmq
snowflake-sqlalchemy
- tantivy
weaviate-client
- aioboto3
pyarrow
lancedb
oracledb
- DuckDB
- pymilvus
- pysolr
- SQLite
- tablestore
- aperturedb
- astrapy
chromadb
- dashvector
falkordb
- jaguardb-http-client
- MySQL
pinecone
clickhouse-connect
- couchdb3
- gcsfs
opendal
opengauss-sqlalchemy
- pyairtable
pyiceberg
pymochow
- pymysql
- pyobvector
- s3fs
singlestoredb
- tcvectordb
typesense
- ElevenLabs
- graphql-core
- jupyter-core
jupyterlab-server
tornado
- Ray
jupyterlab-pygments
- tinycss2
- ipywidgets
- jupyter-server-terminals
- jupyterlab-widgets
- matplotlib-inline
- widgetsnbextension
- argon2-cffi
- argon2-cffi-bindings
- azure-identity
google-auth-httplib2
- msal
- argilla
- azure-ai-agents
- azure-ai-inference
- azure-ai-projects
contextual-client
- diff-cover
- einops
firecrawl-py
friendli-client
- guardrails-ai
llama-cpp-python
llama-index-core
- llama-index-embeddings-dashscope
- llama-index-embeddings-huggingface
- llama-index-embeddings-openai
- llama-index-llms-anthropic
- llama-index-llms-azure-openai
- llama-index-llms-huggingface
- llama-index-llms-llama-cpp
- llama-index-llms-openai
- llama-index-llms-openai-like
- llama-index-node-parser-dashscope
- llama-index-program-guidance
- llama-index-readers-dashscope
- llama-index-readers-database
- llama-index-readers-remote
- llama-index-readers-upstage
- llama-index-readers-web
- llama-index-response-synthesizers-google
- llama-index-utils-azure
- llama-index-utils-huggingface
- llama-index-utils-qianfan
- llama-index-vector-stores-google
- llama-index-workflows
- mem0ai
- ms-swift
- open-clip-torch
- openinference-instrumentation-llama-index
- openvino-tokenizers
- PaddlePaddle
portkey-ai
- reka-api
- tavily-python
- typecast-python
- torch
- transformers
- ibm-watsonx-ai
cohere
- bedrock-agentcore
sentence-transformers
fastembed
- flagembedding
- llama-cloud
optimum-intel
- sentencepiece
- ai21
aleph-alpha-client
- gigachat
- guidance
igptai
- konko
litellm
- mixedbread
- octoai
- openvino
- openvino-genai
premai
- tritonclient
- vLLM
- voyageai
- zep-python
- zhipuai
- agent-search
- aimon
argilla-llama-index
assemblyai
- bm25s
browserbase
cleanlab-tlm
cognee
- colpali-engine
- datasets
- exa-py
flashrank
- hnswlib
honeyhive
- instructorembedding
isaacus
llmlingua
- llmsherpa
- marvin
mlx
- mlx-lm
nomic
notdiamond
optimum
optimum-habana
- paddleocr
peft
presidio-analyzer
promptlayer
- psychicapi
- pydi-client
- rank-llm
- span-marker
- superlinked
tokenizers
uptrain
vectorize-client
videodb
- bleach
camelot-py
- ghostscript
- llama-index-readers-file
- llama-index-readers-youtube-transcript
- maincontentextractor
marker-pdf
mistune
- nbformat
- newspaper3k
nougat-ocr
- pandocfilters
- bs4
- html2text
unstructured
- defusedxml
- filetype
- bagel
- docx2txt
- pytesseract
dgml-utils
docling
- layoutir
- llama-parse
- lxml-html-clean
- markitdown
- nbconvert
- pdf2image
- striprtf
- svglib
tinytag
- youtube-transcript-api
- fastjsonschema
- fqdn
- rfc3339-validator
- rfc3986-validator
docling-core
- python-json-logger
- Alibaba Cloud
- oci
In common
starlette
- asyncpg
- oss2
psycopg
psycopg2-binary
- Redis
- Neo4j
- anyio
- AIOHTTP
- soupsieve
prompt-toolkit
matplotlib
- Rich
- SQLAlchemy
- cryptography
- pyjwt
 OpenAI
opencv-python
- LangChain
- tiktoken
- MCP
dashscope
nltk
chonkie
- ModelScope
- Ollama
- scikit-learn
langfuse
- beautifulsoup4
markupsafe
webencodings
- xlrd
pillow
- jinja2
lxml
pymupdf
- markdownify
olefile
- pdfplumber
pypdf
pypdf2
- tika
- jsonschema-specifications
marshmallow
- referencing
- Pydantic
- annotated-types
- jsonschema
opentelemetry-semantic-conventions
prometheus-client
psutil
- boto3
- OpenTelemetry
MemoryBear
MemoryBear Equip AI with human-like memory capability
Python10.2kRead on November 13, 2026, at commit 9ba1071What is MemoryBear built with?Only in MemoryBear
- FastAPI
- Actix Web
uvicorn
- Flask
- amqp
- py-key-value-aio
- s3transfer
- Celery
- Postgres
kombu
elasticsearch-dsl
valkey
- Elasticsearch
- Hugging Face
werkzeug
- Tokio
fastmcp
- React
react-router-dom
- Vite
- alembic
authlib
- bcrypt
- ecdsa
itsdangerous
- keyring
- python-jose
- passlib
- crcmod
langchain-mcp-adapters
langgraph-sdk
- langsmith
- xinference-client
- LangGraph
langchain-openai
- langid
- langchain-aws
- onnxruntime
- xgboost
- docutils
et-xmlfile
- html5lib
- mako
markdown-it-py
- mdurl
- python-docx
- python-magic-bin
rich-rst
ruamel-yaml
- openpyxl
- python-magic
- markdown
- python-calamine
- python-pptx
- mammoth
- demjson3
- email-validator
- jsonschema-path
- openapi-pydantic
beartype
- Flower
- volcengine-python-sdk
- botocore
tracing
- concurrent-log-handler
- Tailwind CSS
- @codemirror/theme-one-dark
antd
lexical
- AntV
echarts-for-react
- D3
- react-infinite-scroll-component
echarts
dnd-kit
- CodeMirror
- echarts-wordcloud
react-syntax-highlighter
- Mermaid
react-fast-marquee
react-window
- react-markdown
- html2canvas
- js-yaml
pdfjs-dist
rehype-katex
rehype-raw
remark-breaks
remark-gfm
xlsx
Side by side
Frequently asked questions
Which is bigger, llama_index or MemoryBear?
The proof: SuanmoSuanyangTechnology/MemoryBear's code at commit 9ba1071
Which has more GitHub stars, llama_index or MemoryBear?
The proof: run-llama/llama_index on GitHub
Which has more tests, llama_index or MemoryBear?
Which was updated more recently, llama_index or MemoryBear?
The proof: SuanmoSuanyangTechnology/MemoryBear's commits on GitHub
Which has more commits signed by AI, llama_index or MemoryBear?
The proof: the commits each tool signed in SuanmoSuanyangTechnology/MemoryBear
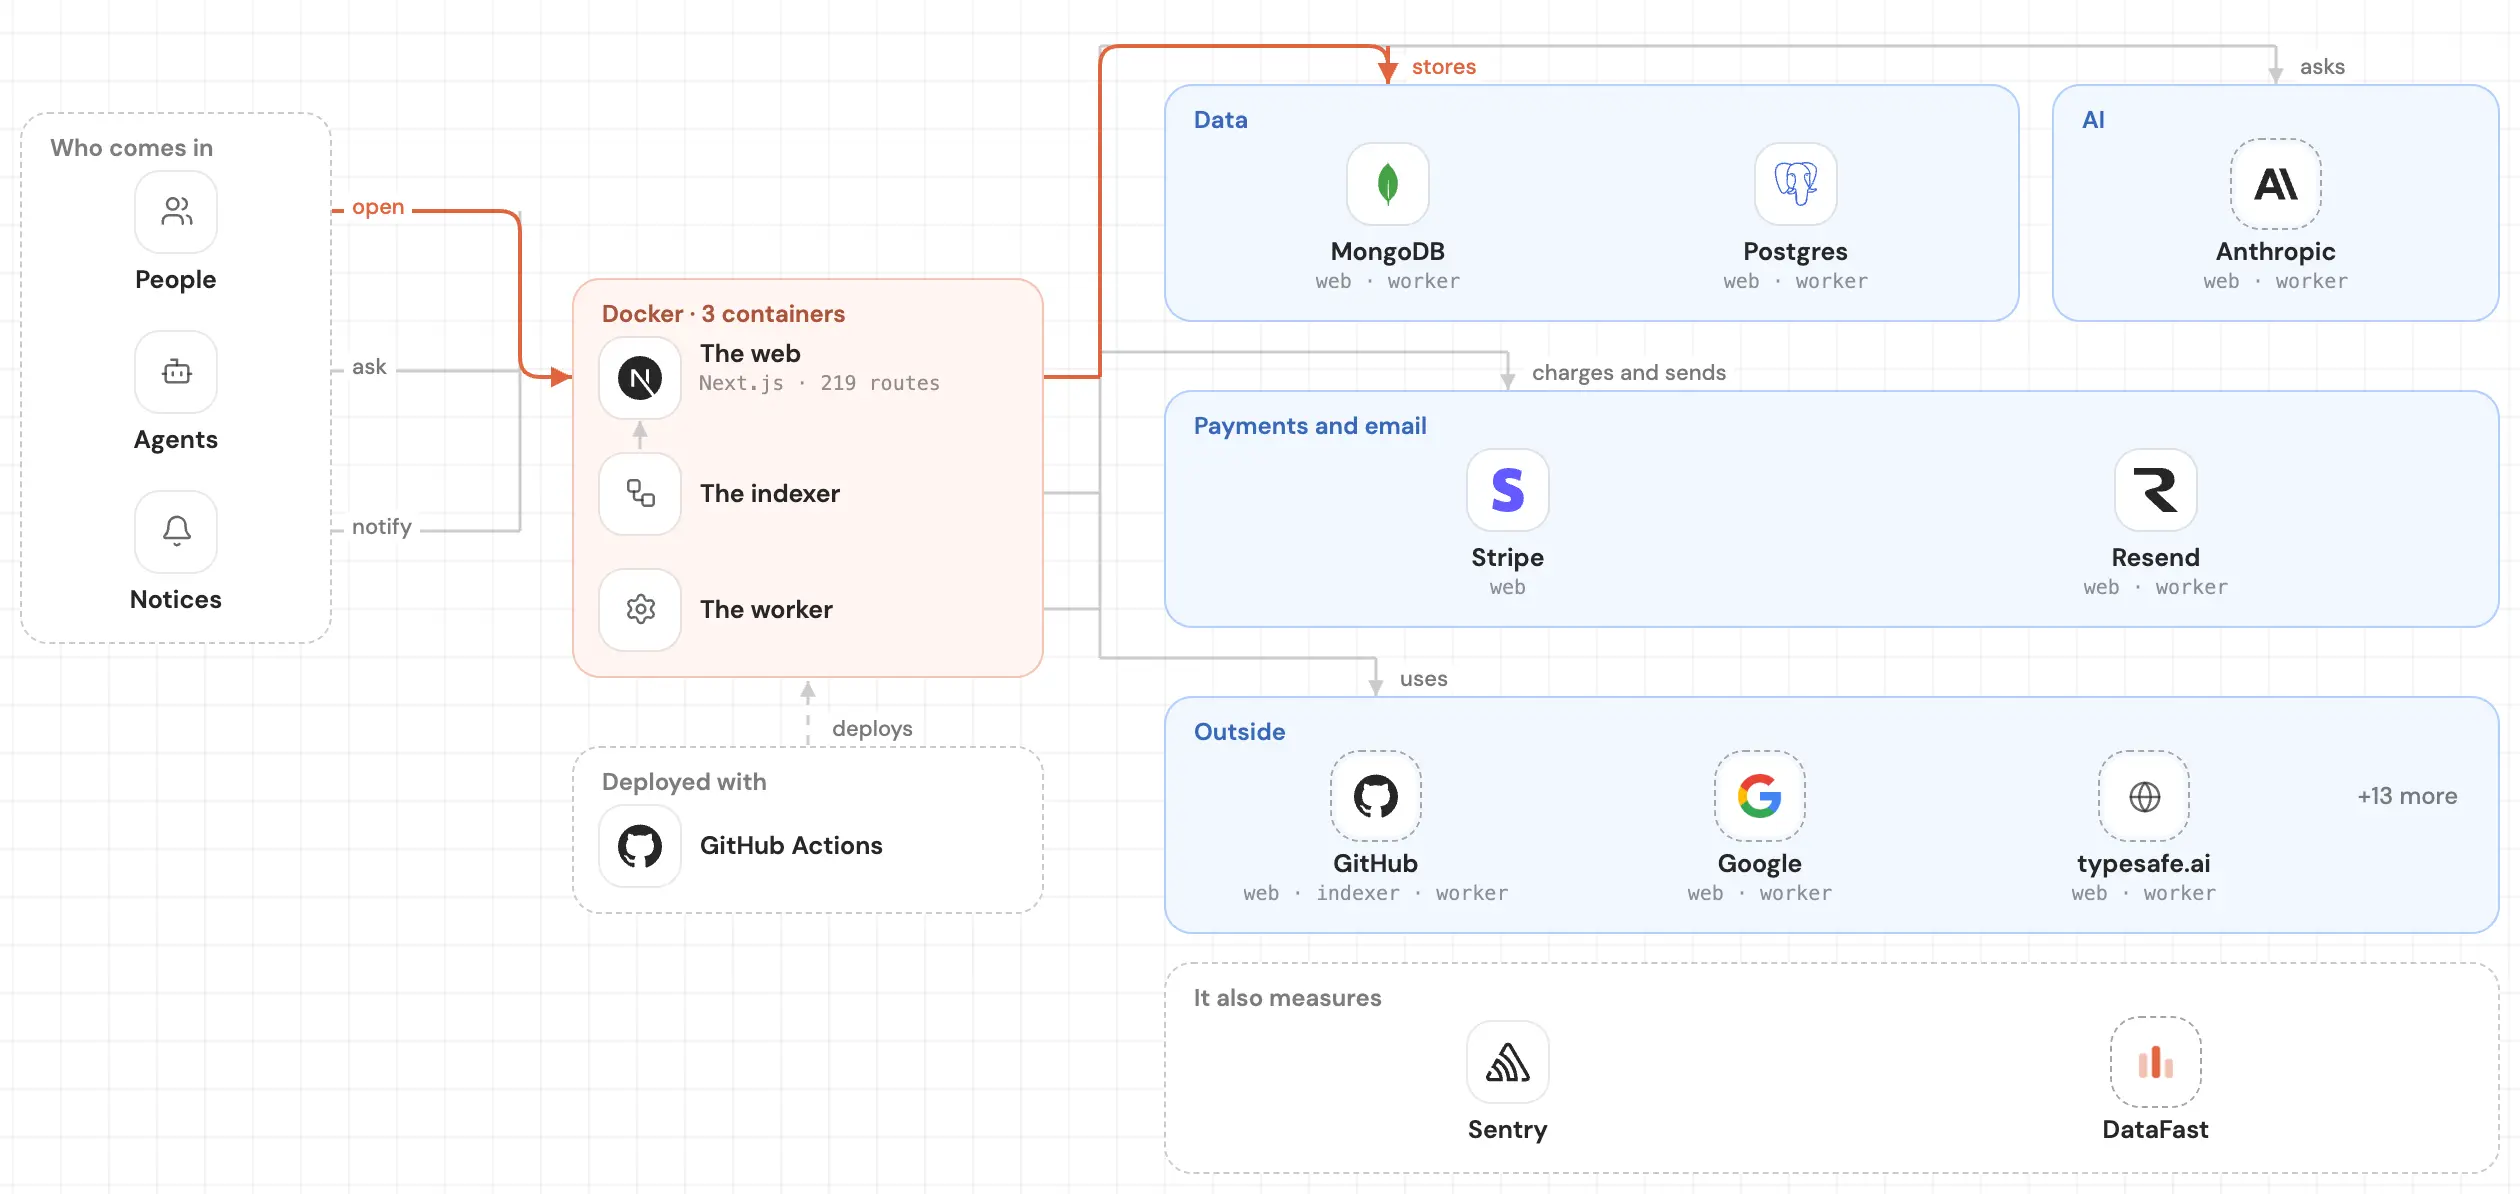
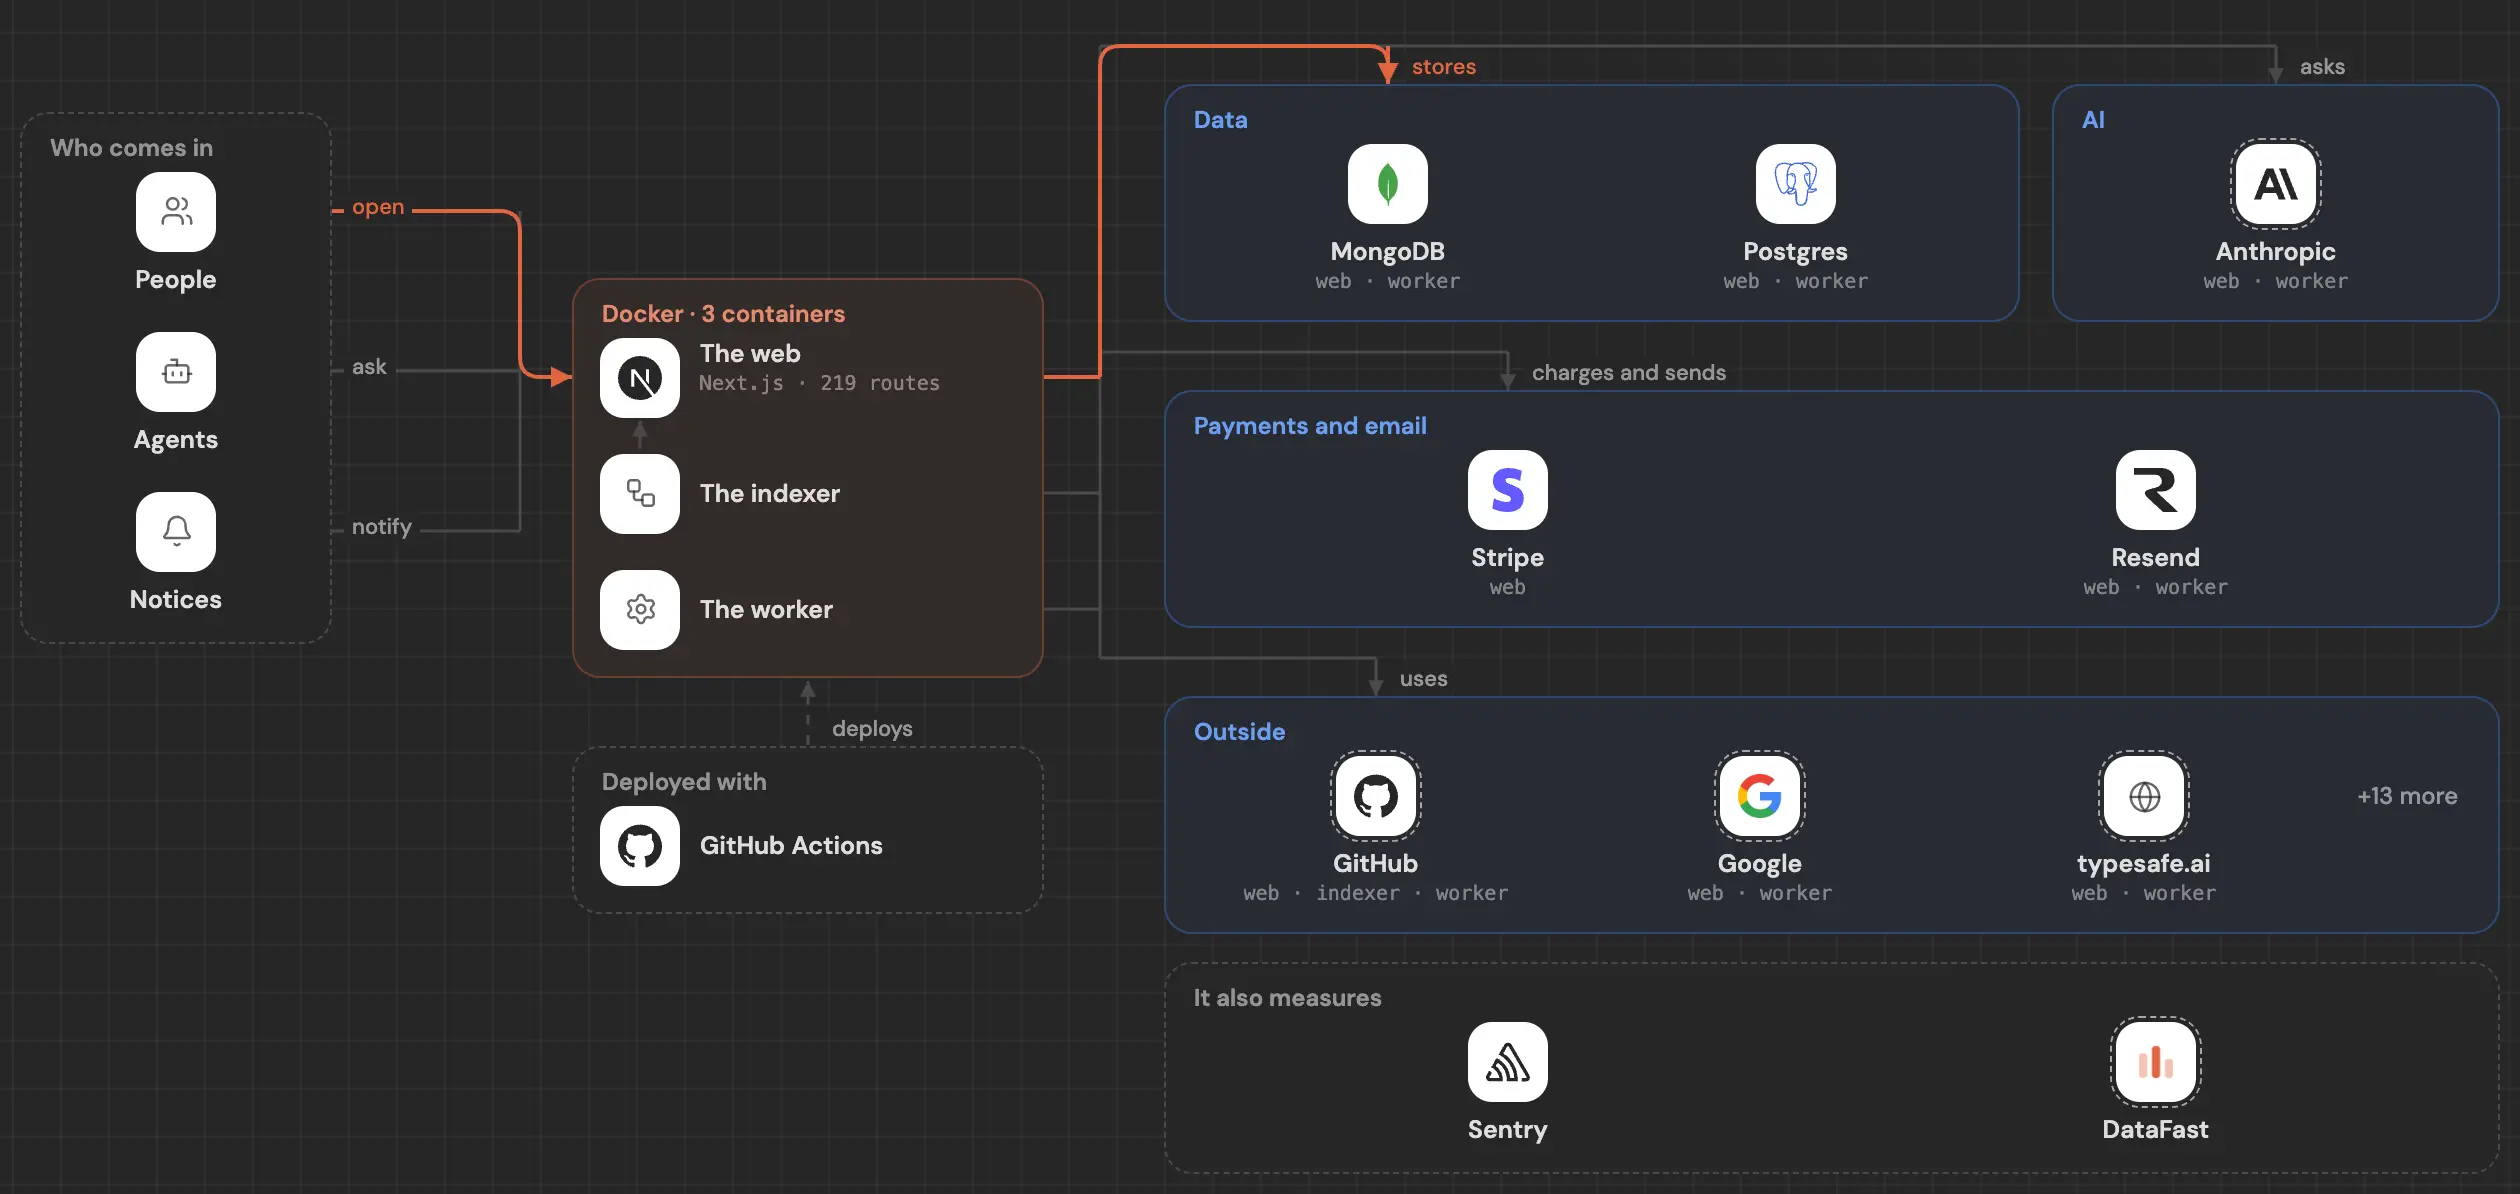
See inside your code, today.
Paste your repo and see it drawn, part by part: a medium one in under a minute.
Free, no account.


